# Data Sampling and Filtering (https://jirametrics.pro/en/docs/core-concepts/data-sampling-and-filtering)
## General Data Sampling Principle [#general-data-sampling-principle]
JiraMetrics.Pro (JMP) uses a unified approach to data sampling for all reports. The plugin gets your board settings and uses them to create a sample of tasks for analysis. By default, JMP includes all tasks that have ever been on the board, in all columns and swimlanes.
## Filtering Tools [#filtering-tools]
JMP offers several tools to refine your sample:
### Swimlanes [#swimlanes]
Allows you to choose specific swimlanes for analysis, helping you focus on certain groups of tasks.
### Quick Filters [#quick-filters]
JMP automatically adds all quick filters from your board, allowing you to use them for additional task filtering. For example, you can use a quick filter to select tasks for a specific team.
### Date Range [#date-range]
Lets you specify a time period for analysis using "from" and "to" fields. This helps you focus on a specific time range.
### Columns [#columns]
Used to choose columns for calculating lead time. In "Activity" filtering mode, this parameter also affects task filtering - only tasks that were active in the selected columns are shown.
### Filtering Mode [#filtering-mode]
Determines how tasks are filtered. Two modes are available: "Activity" and "Completion". You can find a detailed description of these modes in the [Filtering Modes](/en/docs/core-concepts/filtering-modes) article.
### Completion Columns [#completion-columns]
This parameter is only active in "Completion" filtering mode. It allows you to specify which columns, when passed through, mark a task as completed.
## How It All Works Together [#how-it-all-works-together]
1. JMP first gets all tasks from the board.
2. It applies filtering by selected swimlanes (Swimlanes).
3. It applies selected quick filters (Quick Filters).
4. Then it applies the time filter (Date Range).
5. It applies column filtering depending on the chosen filtering mode (Filtering Mode).
6. If "Completion" mode is selected, it considers Completion Columns.
## Usage Example [#usage-example]
Let's say you want to analyze a specific team's work over the last month. Here's how you can use the filters:
1. Choose the swimlane that matches your team's task type.
2. Use the "Team Alpha" quick filter (if you have such a filter on your board).
3. Set the Date Range to the last month.
4. In Columns, choose the columns you want to analyze for task time spent. This will determine which stages of the workflow will be considered when calculating metrics.
5. Choose the appropriate filtering mode (Activity or Completion).
## Usage Recommendations [#usage-recommendations]
* Start with a broad sample, gradually narrowing it down using filters for more detailed analysis.
* Experiment with different filter combinations to get the most useful data for you.
* Use quick filters to quickly switch between different sets of tasks, for example, between different teams or types of work.
* Remember that choosing a filtering mode can significantly affect the analysis results. Make sure you understand the difference between "Activity" and "Completion" modes.
Proper use of filters will allow you to get exactly the data you need for effective analysis and improvement of your work processes.
# Filtering Modes (https://jirametrics.pro/en/docs/core-concepts/filtering-modes)
## What are Filtering Modes? [#what-are-filtering-modes]
**Important:** Filtering modes control **which tasks are included** in your analysis, not **how metrics are calculated**. The calculation formulas for lead time and other metrics remain the same regardless of the filtering mode chosen.
JMP provides two data filtering modes: **"Activity"** and **"Completion"**. The mode is selected through the "Filtering Mode" parameter in the report settings.
## "Activity" Mode [#activity-mode]
In "Activity" mode, tasks are included if they were **active in any of the selected columns** during the specified time period.
### How "Activity" mode works: [#how-activity-mode-works]
* **Inclusion criteria**: A task is included if it had any movement or presence in the selected columns during the timeframe
* **Use case**: Analyzing overall workflow activity and identifying bottlenecks across all stages
* **Data scope**: Broader dataset including tasks that were "in progress" during the period
### When to use "Activity" mode: [#when-to-use-activity-mode]
* General process analysis and workflow overview
* Identifying bottlenecks at all stages of work
* Understanding overall team activity and workload
* Analyzing work in progress (WIP) patterns
## "Completion" Mode [#completion-mode]
In "Completion" mode, tasks are included only if they **completed** (moved through) specified completion columns within the given time period.
### How "Completion" mode works: [#how-completion-mode-works]
* **Inclusion criteria**: A task is included only if it passed through at least one of the specified "Completion Columns" during the timeframe
* **Additional setting**: When this mode is selected, the "Completion Columns" field becomes active, where you specify which columns represent completion
* **Completion logic**:
1. Task must have entered at least one Completion Column within the time period
2. Uses the latest date of entering any Completion Column
3. Tasks that returned to earlier columns after completion are excluded
### When to use "Completion" mode: [#when-to-use-completion-mode]
* Analyzing specific process stages (e.g., development time, testing duration)
* Measuring delivery performance and throughput
* Focusing on completed work rather than work in progress
* Creating delivery forecasts based on historical completion data
## Key Differences Summary [#key-differences-summary]
| Aspect | Activity Mode | Completion Mode |
| ----------------------- | ------------------------------------------- | ----------------------------------------- |
| **Data inclusion** | Tasks active in selected columns | Tasks completed through specified columns |
| **Time reference** | Any activity during period | Completion events during period |
| **Dataset size** | Typically larger (includes WIP) | Typically smaller (completed work only) |
| **Best for** | Process analysis, bottleneck identification | Delivery analysis, throughput measurement |
| **Additional settings** | None | Requires "Completion Columns" selection |
## Impact on Reports [#impact-on-reports]
**All reports use the same filtering mode** you select, ensuring consistent analysis across:
* **Lead Time**: Affects which tasks' lead times are measured
* **Aging Chart**: Affects the data sample used for aging statistics calculations
* **Predictability**: Influences the task sample for predictability calculations
* **Table View**: Controls which tasks are displayed in the detailed view
## When to Use Each Mode [#when-to-use-each-mode]
### Use "Activity" Mode: [#use-activity-mode]
* To analyze tasks that were **active** in selected columns during the time period
* To see all work that was in progress, regardless of completion status
* For process analysis and identifying bottlenecks
### Use "Completion" Mode: [#use-completion-mode]
* To analyze only tasks that **completed** through specified columns during the time period
* To focus on delivered work and measure completion rates
* Requires selecting which columns represent "completion" for your workflow
## Important Notes [#important-notes]
* **Metrics formulas don't change**: Lead time is always calculated the same way regardless of filtering mode
* **Only data selection changes**: Different tasks are included in the analysis, but calculations remain consistent
* **Experiment with both modes**: Try both to understand which gives you more actionable insights for your specific needs
# Metrics and Trends (https://jirametrics.pro/en/docs/core-concepts/metrics-and-trends)
## What the Metrics Block Is [#what-the-metrics-block-is]
In some reports, next to the chart there is a row of cards with key numbers — this is the **metrics block**. Each card shows one value (for example, the median completion time or the number of completed tasks), and some cards have a **trend indicator** next to the value.
The metrics block is present in these reports:
* Lead Time
* Throughput
* Control Chart (Premium)
* Percentile Trend (Premium)
* Flow Efficiency (Premium)
* WIP Run Chart (Premium)
The Aging Chart, CFD, Predictability, and Table View reports have no metrics block.
## What a Card Consists Of [#what-a-card-consists-of]
* **Title** — a short name of the metric (written in capital letters).
* **Value** — the number itself. The main metric of the report is highlighted in blue.
* **Unit** — where applicable: `d` (days), `%`, and so on.
* **Trend indicator** — not present on every card. It is an arrow with a percentage change:
* ↑ — increase,
* ↓ — decrease,
* → — no significant change (or there is no data to compare with — then `N/A` is shown).
## Why an Up Arrow Is Sometimes Green and Sometimes Red [#why-an-up-arrow-is-sometimes-green-and-sometimes-red]
The color depends **not on the direction of the arrow, but on the meaning of the metric**:
* **More is better** (for example, Throughput — the number of completed tasks). An increase is shown in **green**, a decrease in red.
* **Less is better** (for example, completion time, wait time, WIP, a time percentile). An increase is shown in **red**, a decrease in green.
In other words, green always means "a change for the better" and red means "for the worse", regardless of which way the arrow points.
## Two Kinds of Trend [#two-kinds-of-trend]
It is important to understand: in the reports, the word "trend" is calculated in **two different ways**. Do not confuse them.
### 1. Comparison with the Previous Period [#1-comparison-with-the-previous-period]
Where it appears: the **Total Completed** card in the Throughput report.
The current result is compared with a period of the same length that comes **immediately before** the current one.
* **The previous period** is an interval of the same length that ends exactly one millisecond before the current one begins. Example: if the period **March 1–31** is selected, then the previous period is **January 29 – February 28** (the same duration, ending right before March 1).
* **Change formula:**
```
Change, % = (Current − Previous) / Previous × 100
```
* If the previous period was **0**, then any increase is shown as **+100%**.
* Changes of less than **1%** in either direction are considered noise and are shown as "no change" (→).
* The arrow and the color follow the meaning of the metric (see the section about color above).
### 2. Dynamics Within the Selected Period [#2-dynamics-within-the-selected-period]
Where it appears: the **Trend** cards in the Percentile Trend and WIP Run Chart reports, and also the text metric **Trend** in Throughput.
Here the comparison is **not with a separate previous period**, but of the beginning of the selected range with its end:
* **Percentile Trend** — the percentile value in the first period is compared with the last one. A change of more than **5%** in either direction → `Increasing` / `Decreasing`, otherwise `Stable`.
* **WIP Run Chart** — the average WIP over the first quarter of the range is compared with the last quarter (at least 4 days of data are required). The threshold is the same — **5%**.
* **Throughput, the text metric Trend** — this is the direction of the trend line (linear regression) across all periods of the range. It may **not match** the "versus the previous period" arrow on the Total Completed card — this is normal, because these are different calculations: one looks at the dynamics of the whole range, the other compares the last period with the previous one.
## When the Trend Is Not Shown [#when-the-trend-is-not-shown]
If there is nothing to compare with — there is no previous period, or there are fewer than two periods with data — the card shows `N/A` or simply the `→` arrow. A zero change is shown as `→ 0.0%`.
# Timezones and Day Boundaries (https://jirametrics.pro/en/docs/core-concepts/timezones)
## In Short [#in-short]
Every "day" in JMP — a task's completion day, the boundaries of the selected period, the ticks on the time axis — is calculated using your **Jira profile's timezone**, not your computer's or browser's timezone.
In practice, this means:
* A task closed at **31 March in the evening**, by your Jira profile's clock, lands in **March** — even if it's already 1 April by UTC or by your laptop's clock at that moment.
* Report numbers **don't change based on where you physically are**: open JMP while traveling in a different timezone, and you'll see the same numbers as at home.
* Colleagues with the same Jira profile timezone see the same numbers on the same filters.
## How JMP Knows the Timezone [#how-jmp-knows-the-timezone]
The profile timezone comes together with the board configuration from Jira — there's nothing to configure separately. It's the same timezone set in your Jira profile settings (Profile → Time Zone).
## Why It Matters [#why-it-matters]
Task transition history arrives from Jira already in profile time. If JMP interpreted these times using the browser's clock, tasks closed late in the evening would "slip" into the next day — and the number of tasks closed in a month would depend on which timezone you were viewing the report from. The same report would show different numbers to different people.
Anchoring to the Jira profile's timezone removes this ambiguity: a task's day is determined once, the same way Jira sees it.
# Getting to Know Dashboards (https://jirametrics.pro/en/docs/dashboards/overview)
## Overview [#overview]
A **dashboard** is your own metrics page: you decide which charts appear on it and with what settings. If reports are ready-made tools for one-off analysis, a dashboard is a permanent "instrument panel" that you assemble once and then open every day — at standups or process reviews.
How dashboards differ from reports:
* **Several charts on one screen.** No need to switch between reports — your key metrics are visible at a glance.
* **Every widget is configured independently.** One widget can show Lead Time for the whole board, the next one Throughput for bugs only, and a third one a comparison of two teams.
* **Dashboards are saved.** A configured dashboard doesn't go anywhere — it's waiting for you the next time you open JMP, and on paid plans it syncs through the cloud.
* **Dashboards can be shared** with colleagues via a link (see [Sharing Dashboards](/en/docs/dashboards/sharing)).
Full-featured dashboards are an **Expert** plan capability. On the FREE and PRO plans, a demo mode is available: one dashboard with a few basic widgets to try the functionality in practice — see [Dashboards and Plans](#dashboards-and-plans) for details.
{/* SCREENSHOT: общий вид страницы дашборда — несколько виджетов в группах, сайдбар со списком дашбордов слева */}
## Creating Your First Dashboard [#creating-your-first-dashboard]
1. Open the **Dashboards** section in the left sidebar.
2. Click the **Create Dashboard** button (or the "+" next to the section header in the sidebar).
3. Enter a dashboard name — the only required field — and confirm.
A new dashboard is created with one empty group called "Main". From there it's simple: click **Add widget**, pick the widgets you need, and configure them — see [Dashboard Widgets](/en/docs/dashboards/widgets) for details.
{/* SCREENSHOT: модалка Create Dashboard с полем названия */}
## Widget Groups [#widget-groups]
Widgets on a dashboard live in **groups** — horizontal sections with headers. Groups help keep things tidy once you have many widgets: for example, "Delivery Speed", "Process Health", "Team A / Team B".
What you can do with a group:
* **Rename** — click the group title and type a new one (up to 80 characters).
* **Collapse/expand** — handy for temporarily hiding sections you rarely need.
* **Move up/down** — the Move up / Move down buttons in the group menu.
* **Add a widget** — the Add widget button inside the group.
* **Delete** — with confirmation; the group's widgets are deleted along with it.
A new group is added with the **Add Group** button at the bottom of the dashboard. Widgets can be dragged between groups by the widget header.
## Dashboard Date Range [#dashboard-date-range]
The page header contains the **date range picker** — the global time range. By default, every widget on the dashboard follows it: change the range in the header and all charts rebuild for the new period.
At the same time, any widget can "detach" from the shared range and use its own — for example, so that a monthly chart and a quarterly chart sit side by side. Such a widget gets a custom-date badge in its header. See [Dashboard Widgets](/en/docs/dashboards/widgets#widget-date-range-shared-or-custom) for how to set this up.
## Managing Dashboards [#managing-dashboards]
You can have several dashboards — for example, one per team or one per recurring meeting.
* **Switching** — click a dashboard name in the sidebar. The section shows up to 6 dashboards; if you have more, the **View all** link opens the full list.
* **Favorites** — the star to the left of the name pins a dashboard higher in the list.
* **Renaming** — the gear icon in the page header opens **Dashboard Settings**, where you can change the name.
* **Deleting** — the **Delete dashboard** button in the same settings dialog. Before deleting, JMP shows how many groups and widgets the dashboard contains and asks for confirmation — deletion cannot be undone.
{/* SCREENSHOT: сайдбар с несколькими дашбордами, звездочка избранного, счетчик виджетов */}
## Dashboards Belong to a Board [#dashboards-belong-to-a-board]
Every dashboard is tied to the Jira board it was created on. That makes sense: widgets are configured against a specific board's columns, swimlanes, and filters — on a different board, those settings wouldn't mean anything.
This has a few consequences:
* Open a **different board**, and you'll see **that board's** list of dashboards. If you haven't created anything on this board yet, the list will be empty — dashboards from other boards aren't gone, they're waiting for you on their own boards.
* **You can't move or copy a dashboard to another board** — for a new board, a dashboard has to be built from scratch.
* A sharing link also points to a dashboard on a specific board (see [Sharing Dashboards](/en/docs/dashboards/sharing)).
## Dashboards and Plans [#dashboards-and-plans]
Dashboards are an **Expert** plan feature; other plans get a demo mode for exploring the functionality:
| Capability | FREE / PRO | Expert |
| --------------------- | --------------------- | ----------------------------- |
| Number of dashboards | 1 | Unlimited |
| Widgets per dashboard | 3 | Unlimited |
| Widget types | Lead Time, Throughput | All, including premium charts |
| Sharing via link | — | Yes |
The demo mode on FREE and PRO lets you build one dashboard with three basic widgets and see how everything works — but it is a preview, not a working tool. Premium widgets (Control Chart, Flow Efficiency, WIP Run Chart, Percentile Trend) are visible in the list but marked as available in the Expert plan.
If you go over the limit (for example, extra dashboards remain after an Expert trial ends), dashboards switch to **read-only** mode: everything stays visible, but editing is locked until you upgrade — your configured dashboards are not lost.
## Saving and Synchronization [#saving-and-synchronization]
Working with dashboards requires signing in to your JiraMetrics.Pro account. On paid plans, dashboards sync through the cloud: configure a dashboard on your work computer and it will be available on your laptop after signing in to the same account. Synchronization happens automatically — there is no "Save" button to press.
## What's Next [#whats-next]
* [Dashboard Widgets](/en/docs/dashboards/widgets) — widget types, display modes, settings, and datasets.
* [Sharing Dashboards](/en/docs/dashboards/sharing) — how to share a dashboard with your team.
# Sharing Dashboards (https://jirametrics.pro/en/docs/dashboards/sharing)
## Overview [#overview]
You can show a configured dashboard to your team without making everyone rebuild it: share a **read-only link**. The recipient sees the same dashboard with the same widgets and settings — but cannot change anything.
Typical scenarios:
* a team dashboard opened at standups or process reviews;
* a metrics "showcase" for a manager or a neighboring team;
* one canonical dashboard for several people instead of a copy for each.
Sharing is available on the **Expert** plan.
## How to Share [#how-to-share]
1. Open the dashboard you want to share.
2. Click the **Share** icon in the page header.
3. In the **Share Dashboard** dialog, click **Copy Link** and send the link to your colleagues.
{/* SCREENSHOT: диалог Share Dashboard со ссылкой и кнопкой Copy Link */}
## What the Recipient Sees [#what-the-recipient-sees]
The link opens the dashboard in **read-only** mode:
* all widgets are visible with up-to-date data — but the recipient sees **their own** data: whatever they have access to in your Jira;
* editing is unavailable — no settings, no adding widgets, no dragging;
* someone else's dashboard cannot be re-shared.
To view the dashboard, the recipient needs to:
1. have access to the same Jira instance as you (the link is useless to people outside your Jira);
2. sign in to a JiraMetrics.Pro account — if the recipient is not signed in, they will see a sign-in screen.
The recipient does **not** need a paid plan — any signed-in user can view shared dashboards.
## The Link Stopped Working? [#the-link-stopped-working]
If the recipient sees the message "This shared dashboard is unavailable", the dashboard was deleted by its owner, access was revoked, or the link is broken. Ask the owner to send the link again.
## Data Freshness [#data-freshness]
The link points to the "live" dashboard, not a fixed copy: if the owner changes the widgets or settings, recipients see the updated version the next time they open it. The data itself is loaded from Jira by each user independently — the numbers are always current as of the moment of viewing.
# Dashboard Widgets (https://jirametrics.pro/en/docs/dashboards/widgets)
## Overview [#overview]
A **widget** is a single chart or metrics panel on a dashboard. Every widget is a self-contained mini-report: it has its own filter settings, its own display mode, and its own size. This independence is what makes dashboards useful: one screen can hold different metrics with different slices of your data.
## Widget Types [#widget-types]
Widgets are added with the **Add widget** button inside a group. The **Add Widget** window opens with widget cards — you can select several at once and add them in one click.
{/* SCREENSHOT: модалка Add Widget с карточками всех шести типов, часть помечена как премиум */}
Six widget types are available:
| Widget | What it shows | Plan |
| -------------------------- | ---------------------------------------------------------------------------------------- | --------- |
| **Lead Time Distribution** | Histogram of completion times with percentile markers | All plans |
| **Throughput** | Throughput — number of completed tasks per period, with comparison of multiple data sets | All plans |
| **Percentile Trend** | How lead time percentiles change from period to period | Expert |
| **Flow Efficiency** | Ratio of active work to wait time | Expert |
| **Control Chart** | Control chart of cycle times with statistical limits | Expert |
| **WIP Run Chart** | Number of tasks in progress (WIP) and their average age over time | Expert |
Each widget calculates data with the same logic as the report of the same name — see the report pages for detailed methodology: [Lead Time](/en/docs/reports/lead-time-report), [Throughput Chart](/en/docs/reports/throughput-chart-report), [Percentile Trend](/en/docs/reports/percentile-trend-report), [Flow Efficiency](/en/docs/reports/flow-efficiency-report), [Control Chart](/en/docs/reports/control-chart-report), [WIP Run Chart](/en/docs/reports/wip-run-chart-report).
Full-featured dashboards are an Expert plan capability. In the demo mode on the FREE and PRO plans, only Lead Time Distribution and Throughput can be added (up to three widgets per dashboard); premium cards are visible but dimmed — a tooltip explains that the chart is available in the Expert plan.
## Widget Settings [#widget-settings]
Hover over the widget header and click the gear icon — a settings panel opens on the right. Everything you can change about a widget lives here.
{/* SCREENSHOT: панель настроек виджета (drawer) — секции Display Mode, Filters, Chart Options */}
### Title and Group [#title-and-group]
* **Widget Title** — a custom widget name (up to 80 characters). Useful when the dashboard has two widgets of the same type with different filters: name them "Lead Time — bugs" and "Lead Time — features" and there will be no confusion.
* **Group** — moves the widget to another group (the selector appears when there is more than one group). You can also simply drag the widget to another group by its header.
### Display Mode [#display-mode]
The same widget can look different — from a full chart to one big number:
* **Chart Only** — just the chart, maximum space for the visualization.
* **Chart + Metrics** — the chart with a row of key metrics below it.
* **Metrics Panel** — a compact grid of metrics without a chart. Suitable when the numbers matter more than the curve's shape.
* **Hero Metric** — one large metric. Perfect for the single most important number that should be visible from across the room.
For how to read metric cards and trend arrows, see [Metrics and Trends](/en/docs/core-concepts/metrics-and-trends).
{/* SCREENSHOT: один и тот же виджет в четырех режимах отображения рядом */}
### Size [#size]
The dashboard is built on a 12-column grid. The following sizes are available in widget settings:
* **XS** (2 columns) — for the Hero Metric mode only;
* **S** (4 columns), **M** (6 columns), **L** (8 columns), **XL** (full width).
The set of available sizes depends on the display mode: for example, Hero Metric can only be XS or S, while charts range from S to XL. Unavailable sizes are dimmed in the selector.
### Widget Date Range: Shared or Custom [#widget-date-range-shared-or-custom]
The first thing in the **Filters** section is the date range choice:
* **Use dashboard date** (default) — the widget follows the global range from the dashboard header.
* **Custom date range** — the widget gets its own date range and stops reacting to the global one. Such a widget is marked with a custom-date badge in its header — so it's clear that it "lives on its own calendar".
A custom range is handy for comparisons: place two identical widgets side by side — one for "last month", the other for "the month before".
### Data Filters [#data-filters]
Further down in the **Filters** section are the same sampling tools as in reports:
* **Filtering Mode** — Activity or Completion (see [Filtering Modes](/en/docs/core-concepts/filtering-modes)).
* **Columns** — the board columns used for time calculation.
* **Completion Columns** — the completion columns.
* **Swimlanes** and **Quick Filters** — board swimlanes and quick filters.
* **Resolution** — time axis granularity (day/week/two weeks/month), Lead Time Distribution only.
The filter set varies slightly by widget type: for widgets with dataset comparison (Throughput, Control Chart, WIP Run Chart), swimlanes and quick filters are configured not here but inside each dataset — see the next section.
The general principle of how filters work is described in [Data Sampling and Filtering](/en/docs/core-concepts/data-sampling-and-filtering).
### Chart Options [#chart-options]
The **Chart Options** section holds settings specific to the widget type: percentile lines for Lead Time Distribution, period type and the accumulated average line for Throughput, the WIP limit for WIP Run Chart, active work columns for Flow Efficiency, and so on.
## Datasets: Comparison on One Chart [#datasets-comparison-on-one-chart]
The **Throughput**, **Control Chart**, and **WIP Run Chart** widgets can show several data sets on one chart. Each such set is called a **dataset**: it has a name, a color, and its own filters (swimlanes and quick filters).
A typical scenario is comparing teams: a "Team Alpha" dataset with one team's quick filter and a "Team Beta" dataset with another's. The chart shows two lines/series in different colors, and the difference in dynamics is visible immediately.
Datasets are managed in the **Datasets** section of the settings panel:
* **Add** — the Add Dataset button, up to 5 datasets per widget.
* **Name and color** — each dataset gets its own color from the palette; the color can be changed.
* **Filters** — Swimlanes and Quick Filters are selected inside the dataset card. An empty selection means "all tasks".
* **Hide/show** — a dataset can be temporarily hidden from the chart without deleting it (it appears struck through in the list).
* **Delete** — the last remaining dataset cannot be deleted: a widget always needs at least one data set.
{/* SCREENSHOT: секция Datasets с двумя-тремя датасетами разных цветов и график виджета Throughput со сравнением */}
## Interacting with Widgets [#interacting-with-widgets]
* **Dragging** — grab the widget header and drag it to a new position, including into another group.
* **Clicking a dot on the Control Chart** opens the [Task Flow](/en/docs/reports/task-flow) dialog — a breakdown of where a specific task spent its time.
* **Errors don't spread** — if something goes wrong in one widget, the others keep working; the affected widget shows a message and a Retry button.
## Deleting a Widget [#deleting-a-widget]
The **Delete widget** button is at the bottom of the widget settings panel. Deletion cannot be undone, so JMP asks for confirmation.
## Recommendations [#recommendations]
1. **Start small.** Three widgets you actually look at every week beat fifteen added "just in case".
2. **Give widgets meaningful names.** "Throughput — support" is clearer than two identical "Throughput" widgets.
3. **Use Hero Metric for what matters most.** One big number (for example, the P85 completion time) sets the focus for the whole dashboard.
4. **Compare with datasets, not separate widgets** — differences are easier to see on one chart than on two neighboring ones.
# Installation (https://jirametrics.pro/en/docs/getting-started/installation)
## System Requirements [#system-requirements]
* Chromium-based browser (Chrome, Edge, Yandex, Opera, etc.)
* Access to Jira
## Installation Process [#installation-process]
1. Go to the [Chrome Web Store](https://chromewebstore.google.com/detail/jira-metrics-plugin/ehhncnkhbchjllmnbcfebjllhnkgnfpc).
2. On the extension page, click the "Install" button.
3. Confirm the installation if your browser asks for permission.
4. After the installation is complete, you'll see the JMP icon in your browser's extension panel.
## Verifying the Installation [#verifying-the-installation]
Open Jira and go to any task board.
On Jira Server and Data Center, two buttons appear on the board page:
* An **Analyze Metrics** button in the top right corner of the board.
* An **Analyze Metrics** item in the left sidebar menu, next to Reports.
If you can see these buttons, JMP is successfully installed and ready to use.
The button doesn't appear on every board — this is normal and does not affect your work. While on a board, click the JMP icon in the Chrome extension panel and the dashboard opens automatically. From then on, you can open any board the same way.
Right after installation, clicking the icon opens a window with a short guide:
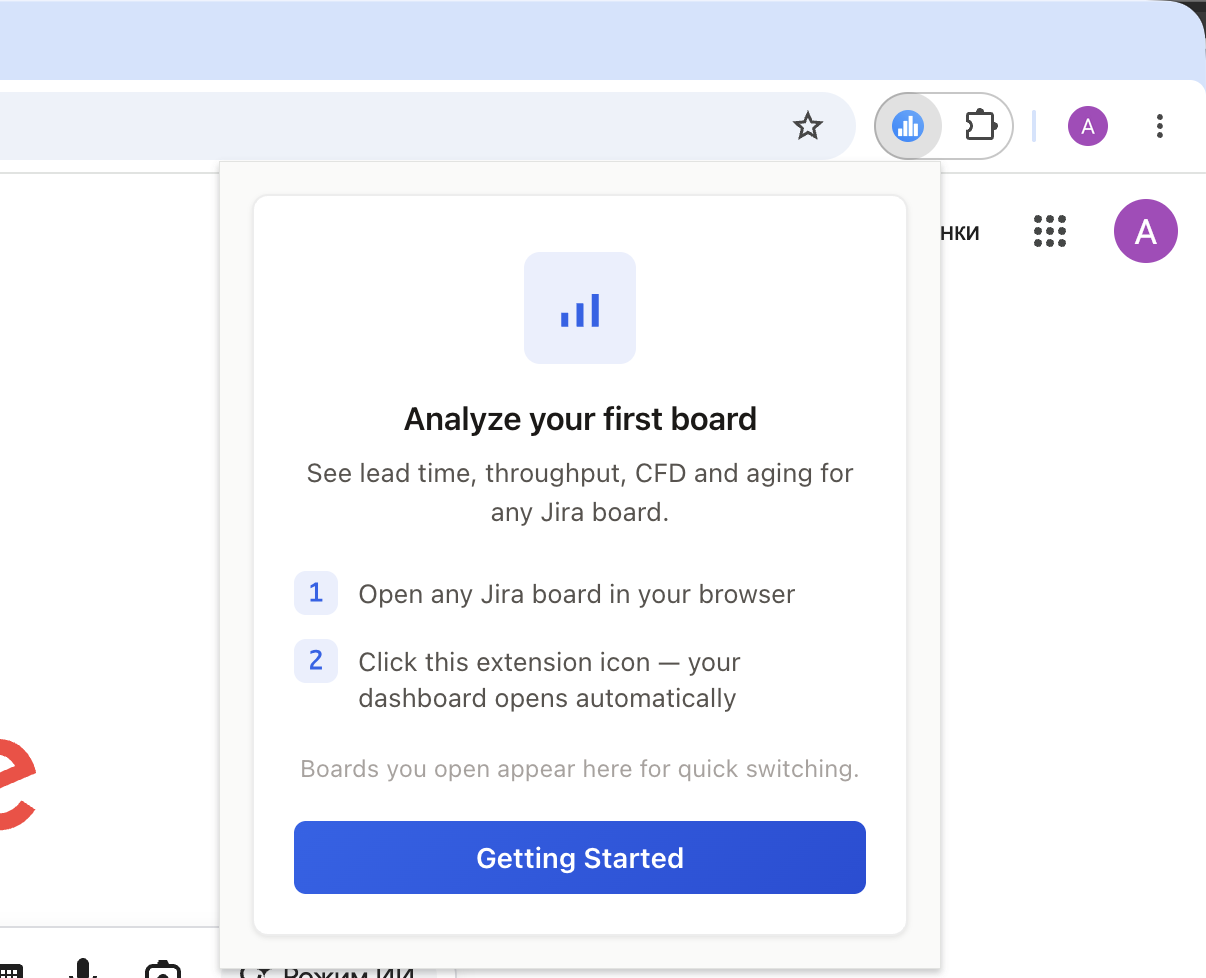
The boards you have opened are remembered and appear in this window — you can quickly switch between them.
## Troubleshooting [#troubleshooting]
If the JMP buttons don't appear on a Jira Server or Data Center board:
1. Make sure the extension is enabled in your browser settings.
2. Try refreshing the Jira page.
3. If the problem persists, try disabling and re-enabling the extension.
If you experience any other installation issues, please contact us at **[support@jirametrics.pro](mailto:support@jirametrics.pro)**.
# Introduction (https://jirametrics.pro/en/docs/getting-started/introduction)
## Overview [#overview]
JiraMetrics.Pro (JMP) is a powerful tool for collecting and analyzing production metrics based on Jira data. It provides a convenient way to address the following tasks:
* Collecting key flow metrics
* Analyzing and identifying process bottlenecks and growth points
* Generating reports on the production system
* Building your own dashboards out of widgets with the metrics you need
* Making data-driven decisions about changes
## Who JMP is for [#who-jmp-is-for]
JMP will be useful for any professionals who systematically work on improving value delivery processes in an intellectual environment.
## Key Benefits [#key-benefits]
* **Ease of use**: JMP doesn't require dedicated infrastructure, servers, or maintenance. It works in any Chromium-based browser (Chrome, Edge, Yandex, Opera, etc.).
* **Independence**: You won't need to involve a Jira administrator or assign tasks to colleagues to start using the tool.
* **Flexibility**: JMP offers various types of reports and data filtering options, allowing you to get exactly the information you need.
* **Visualization**: The tool provides clear graphs and charts that help you quickly assess the state of processes and identify issues.
In this documentation, you'll find a detailed description of all JMP functions, instructions for installation and use, as well as recommendations for interpreting the data obtained.
# Approach to Metrics (https://jirametrics.pro/en/docs/getting-started/philosophy)
## Why this page exists [#why-this-page-exists]
A tool shapes the questions you ask. Open a typical story-point report, and the conversation turns to estimates and "team velocity". Open JMP, and the conversation turns to how much time tasks actually spend in the process, and where they wait.
That's not an accident. JMP is built on a **flow approach** — a view of work as a stream of tasks moving through a system. This page explains the principles baked into the product, so you use it deliberately instead of just "looking at charts".
It's written for anyone trying to improve how work gets done — their own or their team's: team leads, agile coaches, project managers, CTOs.
## We measure reality, not estimates [#we-measure-reality-not-estimates]
JMP has no story points, no velocity, no burndown charts — and that's deliberate.
An estimate is an opinion given before the work starts. Lead time is a fact measured after. Teams spend hours on planning poker, then compare progress against their own guesses. JMP takes a different path: look at **how long tasks actually take to move through the process**. This data already exists in Jira — you don't need to ask anyone for it, and it can't be "over- or under-estimated".
How this shows up in the product: every report is built on the actual history of task movement — Lead Time, Throughput, WIP, CFD. There isn't a single field for manually entering an estimate.
## Distributions, not averages [#distributions-not-averages]
"A task takes 8 days on average" is a sentence that hides more than it reveals. Behind that average could be half the tasks finishing in 3 days and a tail stretching out to 40.
JMP shows **distributions and percentiles** everywhere: P50 (median), P85, P95. Instead of a falsely precise "it'll be done in 8 days", you get an honest "85% of tasks like this finish in 12 days or less". That's a probabilistic promise, and it's the only honest kind — the future isn't deterministic, and it should be talked about in the language of probabilities.
How this shows up in the product: the Lead Time histogram with P50/P85/P95 lines, the Control Chart with percentile bands, and the Percentile Trend report, which is aimed squarely at how percentiles move over time.
## Data has to be honest [#data-has-to-be-honest]
Jira's transition history is sometimes incomplete. Most tools quietly draw a confident number over the gaps. JMP does the opposite: if part of a task's timeline had to be reconstructed, you'll see a "reconstructed" mark and a "lead time is approximate" warning.
The principle is simple: **an honestly approximate number beats a precise-looking but unreliable one**. Decisions made on beautiful but fake precision cost more than decisions made while consciously working with uncertainty.
How this shows up in the product: reconstruction marks and warnings in the [Task Flow](/en/docs/reports/task-flow) dialog, and a separate count of excluded tasks in reports instead of silently dropping them.
## Facts, not accusations [#facts-not-accusations]
JMP deliberately avoids attaching labels. A task moving backward on the board is shown as a "return" — not as "rework": it might be a defect, or it might be a normal part of the review cycle. A long-sitting column is shown as the "longest stage" — not as a "bottleneck": a diagnosis requires context the tool doesn't have.
The tool shows **what happened**. What it means and what to do about it is for the team to decide, because they know their own context. Metrics are material for a conversation, not a verdict.
And most importantly: **metrics aren't a whip**. Flow data exists to improve the system of work, not to pressure people. The moment a metric becomes a tool for punishment, it stops reflecting reality — people start optimizing the number instead of the work. That's why JMP measures the process — columns, queues, wait time — not individual performance.
## Metrics for decisions, not reports [#metrics-for-decisions-not-reports]
A report nobody discusses and that never changes anything is wasted time, no matter how many charts it has.
JMP is designed for a regular practice: open it during a process review, notice a change, discuss the cause, agree on an experiment, check the effect a month later. Every report answers a specific question: "how long does it take?" (Lead Time), "how much do we get done?" (Throughput), "where does work pile up?" (CFD, WIP), "what's stuck?" (Aging). If a report doesn't lead to a question or a decision, it isn't needed — however nice it looks.
How this shows up in the product: the Task Flow dialog with a copy-summary button for retros, [dashboards](/en/docs/dashboards/overview) as a permanent panel for recurring meetings, and trends against the previous period on every metric.
## You can start today [#you-can-start-today]
Process improvement often gets postponed until "we clean up Jira first" or "we roll out the right process". A flow approach lets you skip the wait: your board is already generating flow data — every time a task moves between columns, it's recorded.
JMP takes that data as-is: no dedicated infrastructure, no Jira administrator, no changes to your team's process. Install the extension, and a minute later you're looking at the real picture. You might not like what you see — but that's already the start of improvement, not a delay of it.
## Where to start [#where-to-start]
1. [Quick Start](/en/docs/getting-started/quick-start) — open your board and look at Lead Time and Throughput.
2. Find one thing that surprises you — a long tail in the distribution, a growing WIP, an outlier task.
3. Bring it to your next retro — not as an accusation, but as a question.
Everything after that is a matter of doing it regularly.
# Quick Start (https://jirametrics.pro/en/docs/getting-started/quick-start)
## Opening JMP [#opening-jmp]
1. Open your board in Jira.
2. Click the **JMP icon in the browser toolbar** — or the **Analyze Metrics** button, if it's on the board.
3. JMP opens in a new tab with your board's data.
The extension icon is the most reliable way in — it works on any board. The **Analyze Metrics** button may be missing on Jira Cloud boards — that's normal.
All the ways to launch JMP (including the popup with your recent boards) are described in [Entry Points and Popup](/en/docs/getting-started/toolbar-popup).
## Navigation [#navigation]
On the left is a sidebar with three sections:
* **Reports** — the full list of reports; click a name to open it.
* **Dashboards** — your own metrics panels made of widgets.
* **Settings** — language, theme, and other options.
{/* SCREENSHOT: интерфейс JMP — сайдбар с секциями Отчёты и Дашборды, открытый отчет */}
The fastest way to get around is the **command palette**: press **⌘K** (on Windows, **Ctrl+K**), start typing a report or dashboard name, and press Enter.
## Choosing a Report [#choosing-a-report]
The Reports section includes: **Lead Time**, **Throughput**, **Aging Chart**, **CFD** (Cumulative Flow Diagram), **Predictability**, **Table View** (a table of tasks), plus premium reports — **Control Chart**, **Percentile Trend**, **Flow Efficiency**, and **WIP Run Chart**.
If you're just getting started, begin with **Lead Time** (how long tasks take) and **Throughput** (how many tasks get completed per period) — the two most intuitive reports.
## Setting Up Filters [#setting-up-filters]
Above the report is a filter bar:
1. Choose the time period to analyze.
2. Specify the board columns you need.
3. If needed, pick specific swimlanes or quick filters.
For more on how filters shape which tasks are selected, see [Data Sampling and Filtering](/en/docs/core-concepts/data-sampling-and-filtering).
## Analyzing Data [#analyzing-data]
Study the generated report. Pay attention to:
* General trends
* Anomalies or outliers
* Alignment with expectations and target indicators
Clicking a task in almost any report opens the [Task Flow](/en/docs/reports/task-flow) dialog — a breakdown of exactly where that task spent its time.
## Taking Action Based on Data [#taking-action-based-on-data]
Based on the information you gather, you can:
* Identify areas for improvement
* Spot bottlenecks in processes
* Make informed decisions on workflow optimization
## Next Steps [#next-steps]
* Explore the documentation pages for each report type — they explain how to read the charts and how the numbers are calculated.
* Build your own metrics panel out of widgets — see [Getting to Know Dashboards](/en/docs/dashboards/overview).
Remember to regularly conduct analysis using JMP to track progress and identify new opportunities for process improvement.
# Entry Points (https://jirametrics.pro/en/docs/getting-started/toolbar-popup)
## Overview [#overview]
There are three ways to open JMP: the **Analyze Metrics** button right on a Jira board, clicking the **extension icon** in the browser toolbar, and the **popup** with a list of recent boards. All three lead to the same application — use whichever is convenient at the moment.
## The Analyze Metrics Button on a Board [#the-analyze-metrics-button-on-a-board]
When you open a board in Jira, the extension adds an **Analyze Metrics** button to the page:
* **Jira Server / Data Center** — a button in the board toolbar, plus a matching item in the left sidebar menu (next to Reports);
* **Jira Cloud** — a button next to the board name.
Clicking the button opens JMP for the current board in a new tab.
{/* SCREENSHOT: доска Jira с кнопкой Analyze Metrics в панели инструментов */}
### If There's No Button (Common on Jira Cloud) [#if-theres-no-button-common-on-jira-cloud]
On **Jira Cloud**, the button **doesn't appear on every board** — that's not a plugin bug or a problem with your access.
The fix is simple and always works: **click the JMP icon in the browser toolbar** while you're on the board page. The plugin opens for that exact board, just as it would from the button. The board button is just a convenient shortcut; the extension icon remains the primary, reliable entry point.
If you don't see the icon, open the extensions menu (the puzzle-piece icon next to the address bar) and pin JMP — then the icon is always within reach.
## The Extension Icon [#the-extension-icon]
The behavior of the JMP icon in the browser toolbar depends on where you are:
* **You're on a Jira board** — clicking the icon opens JMP for that board right away, no extra steps.
* **You're on any other page** — clicking it opens the popup with your recent boards.
## The Popup: Quick Switching Between Boards [#the-popup-quick-switching-between-boards]
The popup is a launcher: a list of boards you've already opened in JMP, with search and keyboard navigation (arrow keys and Enter). Each board shows its name and Jira domain. Click one, and it opens in a new tab.
{/* SCREENSHOT: попап расширения со списком недавних досок и полем поиска */}
How the list works:
* A board is added to the list the first time you **open it in JMP** (for example, via the Analyze Metrics button) — nothing needs to be added manually.
* The list keeps up to 10 recent boards, newest first.
* The **Search boards** field filters the list by name and domain — handy once you have a lot of boards.
The popup doesn't require signing in to an account — it works right after you install the extension. It's rendered in the same theme (light or dark) selected in the app.
## First Launch [#first-launch]
If you haven't opened any board yet, the popup shows a short two-step guide:
1. Open any Jira board in your browser.
2. Click the extension icon — the dashboard opens automatically.
After that, the board appears in the popup's list, and you can switch to it from any page. The **Getting Started** button in this window links to the [Installation](/en/docs/getting-started/installation) page.
{/* SCREENSHOT: пустое состояние попапа с онбординг-инструкцией */}
# Data and Privacy (https://jirametrics.pro/en/docs/help/data-privacy)
## The Core Principle [#the-core-principle]
Flow metrics need just two things: **the issue key and the moments it moved between columns**. That's enough to calculate lead time, throughput, CFD, and everything else.
That's why **JMP never requests task titles, descriptions, comments, or assignees**. They don't enter the plugin for a single moment — which means the content of your tasks simply has nowhere to leak from: it isn't in JMP.
The transition history itself is loaded from your Jira straight into your browser, and every metric is calculated on your own computer.
## What Gets Sent, and Where [#what-gets-sent-and-where]
| Destination | What's sent | When |
| -------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------ | ---------------------------------------- |
| **Your Jira** | Requests for board configuration and task transition history — using your own Jira session | When loading a board and its reports |
| **JMP Cloud (account)** | Sign-in profile and dashboard configuration: dashboard and widget names, chosen chart types, column/swimlane/filter IDs, date ranges | If you're signed in and use dashboards |
| **Analytics (Google Analytics)** | Anonymous interface usage events (for example, "report opened", "widget created") with a random installation identifier | In the background, while you use the app |
More detail on each destination:
* **Jira.** JMP talks only to your own Jira instance, and only for two things: the board configuration and the history of tasks moving between columns. It uses your current browser Jira session — JMP never requests or stores separate tokens or passwords.
* **JMP Cloud.** The cloud stores the **configuration** of your dashboards, so they're available from any computer and via sharing links. This is metadata: widget names and which filters are selected in them. The tasks themselves and their timings are never written to the cloud.
* **Analytics.** Events describe actions in the interface: which report was opened, which widget type was created, which filter was clicked. They contain no address of your Jira, no board name, and no task keys; the only Jira-related value that can appear is the numeric identifier of the quick filter you clicked. The installation identifier is random and isn't tied to your account or your Jira.
## What This Means in Practice [#what-this-means-in-practice]
When a company asks whether the extension is safe to install, the concern is usually the same: could the wording of tasks, the discussion in comments, and who is working on what get out? With JMP the answer is short — **the plugin never receives that data**. It sees that `PROJ-123` moved from one column to another at a certain moment, and nothing more.
## What's Stored on Your Computer [#whats-stored-on-your-computer]
Locally (in browser storage) live: the Jira address and board number, the loaded board structure (column, swimlane, and quick filter names), selected filters and date range, the list of recent boards, favorite dashboards, theme, and interface settings. If you clear your browser data:
* settings and filters reset to their defaults;
* **dashboards aren't lost** — they're stored in the cloud and come back once you sign in;
* the transition history is loaded from Jira again the next time you open the app.
# FAQ and Troubleshooting (https://jirametrics.pro/en/docs/help/faq)
## Loading Errors [#loading-errors]
### "Failed to Load Board" [#failed-to-load-board]
JMP couldn't get the board configuration from Jira. Typical causes:
1. **Your Jira session expired.** Click **Open in Jira**, make sure the board opens (sign in to Jira again if needed), then come back and click **Retry**.
2. **No access to the board** — ask the board administrator for access.
3. **The board doesn't exist** — for example, the link points to a deleted board.
Below the error description you'll see a technical response code (for example, `401` or `502`) — it's useful if you contact support.
### "Failed to Load Board Data" [#failed-to-load-board-data]
The board configuration loaded, but the task data didn't. This is usually a temporary Jira outage or lost access. Follow the same steps: **Open in Jira** → confirm the board opens → **Retry**.
### "Loading Board…" Spins for a Long Time [#loading-board-spins-for-a-long-time]
On large boards with a long history, loading task data takes noticeably longer — Jira has to return the entire transition history. This is normal on the first open; switching between reports and widgets afterward reuses already-loaded data and happens fast. If loading is clearly stuck, refresh the page.
## Empty Reports [#empty-reports]
### A Report or Widget Shows "No Data" [#a-report-or-widget-shows-no-data]
Check, in order:
1. **The period.** There may have been no completed tasks in the selected range — widen the period.
2. **Filters.** The combination of swimlanes and quick filters may have filtered out every task — reset the filters and narrow the selection again.
3. **Columns.** Make sure the right columns are selected, along with **Completion Columns** — without them, no task counts as completed. For more, see [Data Sampling and Filtering](/en/docs/core-concepts/data-sampling-and-filtering) and [Filtering Modes](/en/docs/core-concepts/filtering-modes).
When you switch between boards, JMP automatically reconciles saved filters against the current board, so "leftover" filters from another board shouldn't empty out your reports. If that still happens, reset the filters manually.
### Numbers Are Off by a Day [#numbers-are-off-by-a-day]
A task's completion day is calculated using your Jira profile's timezone, not your computer's clock — see [Timezones and Day Boundaries](/en/docs/core-concepts/timezones).
## Buttons and Navigation [#buttons-and-navigation]
### There's No Analyze Metrics Button on a Jira Board [#theres-no-analyze-metrics-button-on-a-jira-board]
**Immediate fix:** while on the board page, click the **JMP icon in the browser toolbar** — the plugin opens for that board even without the button. This always works, regardless of Jira's version or layout.
Why the button might be missing:
* **You're on Jira Cloud.** There the button doesn't appear on every board — this is expected and doesn't get in your way: use the extension icon instead.
* **You're not on a board page** but on the backlog, a single issue, or another Jira section. Go back to the board.
* **The page hasn't fully loaded.** Refresh it — the button appears once the board finishes loading.
* **The extension is disabled.** Check `chrome://extensions/`.
All entry points are described in [Entry Points: Buttons and the Extension Popup](/en/docs/getting-started/toolbar-popup).
### Dashboards Disappeared [#dashboards-disappeared]
You most likely opened a **different board**: dashboards belong to a specific board, and each board has its own list. Go back to the board where you created the dashboards — they're still there. For more, see [Dashboards Belong to a Board](/en/docs/dashboards/overview#dashboards-belong-to-a-board).
If dashboards disappeared on the same board, make sure you're signed in to the same JiraMetrics.Pro account.
### A Shared Dashboard Link Won't Open [#a-shared-dashboard-link-wont-open]
See [Sharing Dashboards](/en/docs/dashboards/sharing#the-link-stopped-working) — usually the dashboard was deleted by its owner, or you don't have access to the same Jira instance.
## Compatibility [#compatibility]
### Which Jira Versions Are Supported [#which-jira-versions-are-supported]
Both **Jira Cloud** and **Jira Server / Data Center** — the plugin works the same way in each.
### Which Boards Work Best [#which-boards-work-best]
JMP is built around flow metrics (Lead Time, Throughput, WIP, CFD) and shines the most on **Kanban boards**. It also works on Scrum boards — metrics are calculated from the same task-movement data.
## Didn't Find an Answer? [#didnt-find-an-answer]
Write to **[support@jirametrics.pro](mailto:support@jirametrics.pro)** — the address is also listed in the app, under Settings. Attach a screenshot of the error and the technical code from the red card, if there is one — it helps us sort things out faster.
# Aging Chart Report (https://jirametrics.pro/en/docs/reports/aging-chart-report)
## Overview [#overview]
The Aging Chart is one of the key flow management tools in the Kanban method, designed to visualize the time tasks spend in progress.
The aging chart shows how long work items remain in the system and is a critically important tool for identifying blocked items and managing delivery risks.
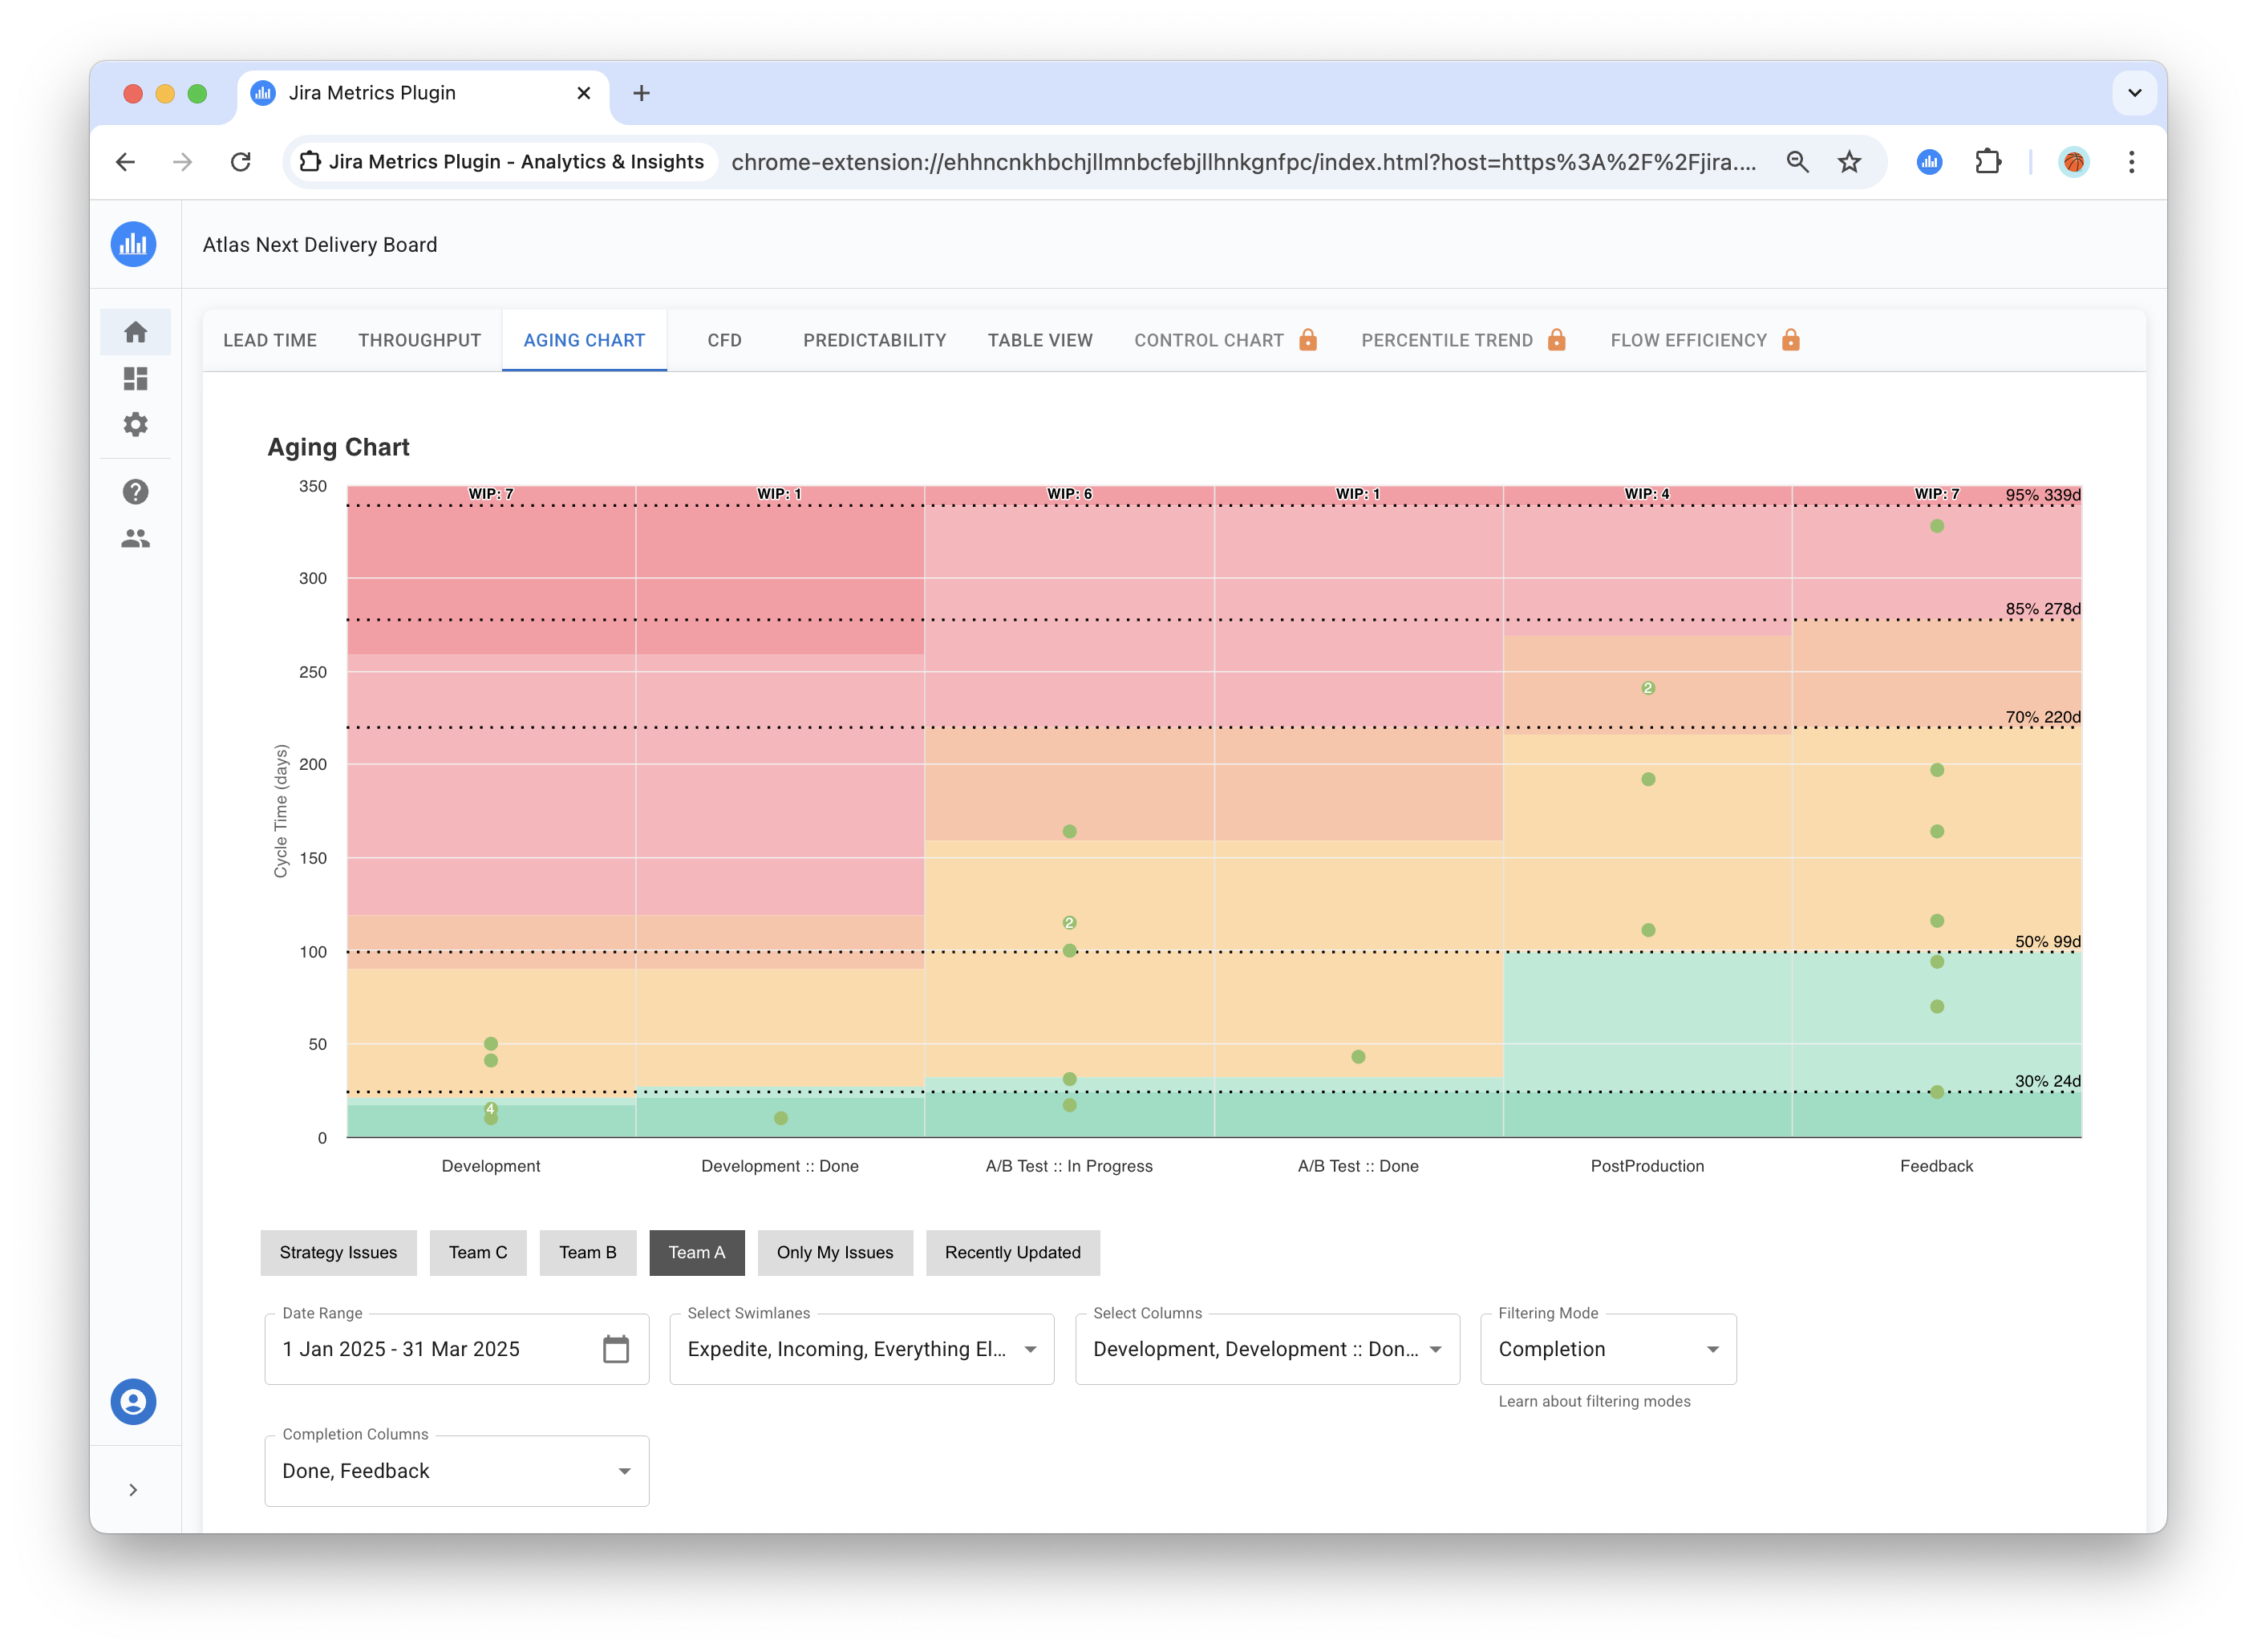
The chart helps teams:
* **Identify risks** of not meeting deadline commitments
* **Find blocked tasks** before they become critical
* **Manage stakeholder expectations** based on data
* **Make decisions** about prioritization and escalation
**Key Principle**: The chart shows current tasks in progress against historical statistics, allowing you to understand which tasks are progressing at a normal pace and which require attention.
## How the Chart Works [#how-the-chart-works]
The Aging Chart is built on two types of data that provide a complete picture of what's happening:
### 1. Current Tasks in Progress [#1-current-tasks-in-progress]
These are all tasks currently being processed on your board. These tasks are displayed as dots on the chart. Each dot shows how many days a task has been in progress.
### 2. Historical Statistics for Comparison [#2-historical-statistics-for-comparison]
To understand whether the current work pace is normal or problematic, the chart uses statistics from previously completed tasks. This statistics creates **color zones** and **horizontal reference lines** on the chart.
**How to configure historical data:**
Historical statistics are automatically calculated based on:
* **Selected time period** (e.g., last 3 months)
* **Applied filters** (projects, task types, teams)
* **Selected workflow columns**
By changing these settings through filters, you can compare current work with different periods or conditions from the past, gaining more accurate understanding of performance.
## How to Read the Chart [#how-to-read-the-chart]
### Chart Axes [#chart-axes]
* **Horizontal axis (X)**: Your Jira workflow columns
* **Vertical axis (Y)**: Task execution time in days
### Tasks on the Chart [#tasks-on-the-chart]
Each task currently in progress is shown as a **teal dot**:
* **Higher position** = longer time in progress
* **Number on dot** = shows task count if multiple tasks have the same time
* **Click on dot** = opens detailed task information
Visualizing the time items spend in the system is critically important for understanding delivery predictability and identifying process anomalies.
## Interactive Elements [#interactive-elements]
### Tooltip Information [#tooltip-information]
When hovering over a dot, a tooltip displays:
* Task key(s) (clickable links)
* Accumulated time for each task in days
* Multiple grouped tasks are listed separately
### Task History Dialog [#task-history-dialog]
Clicking on a task key in the tooltip opens the [Task Flow](/en/docs/reports/task-flow) dialog — a detailed task history showing the task's journey through workflow columns. Inside the dialog you can page through tasks back and forth.
## Chart Settings [#chart-settings]
### Selecting Reference Lines [#selecting-reference-lines]
Using the **Pace Percentiles** selector, you can configure which historical reference points (percentile lines) to show on the chart:
* **Available options**: 30%, 50%, 70%, 85%, 95%
* **Multiple selection** possible — choose several lines at once, or only those important for your team
* **Default**: all five lines are shown
## Color Zones and Reference Lines [#color-zones-and-reference-lines]
The chart shows **colored bands** and **horizontal lines** that help understand how current tasks are performing:
### What Color Zones Mean [#what-color-zones-mean]
Color zones are calculated **separately for each column** based on accumulated time of tasks in that column from historical data:
* **Green zones** (light shades) — tasks are executing faster than usual for this column ✅
* **Yellow-orange zones** — tasks are executing at normal pace for this column ⚠️
* **Red zones** — tasks are executing slower than usual for this column, require attention 🚨
**Calculation specifics**: Each column considers **accumulated time** — the total time a task has spent from process start to the current column. Therefore, color zones become "higher" in subsequent columns, reflecting the natural increase in total execution time.
### Percentile Lines [#percentile-lines]
Horizontal lines show historical reference points:
* **30%, 50%, 70%, 85%, 95%** — statistical markers from past experience
* If a task is **above the 85% line** — it's executing slower than 85% of similar tasks in the past
* If a task is **below the 50% line** — it's executing faster than half of similar tasks
Important to understand: percentiles in the aging chart are not a plan, but a risk indicator. They help the team understand when to pay attention to a task and take action.
**Important to remember**: Colors and lines may differ for different columns because statistics are calculated separately for each work stage.
## Available Filters [#available-filters]
The Aging Chart includes comprehensive filtering options:
### Filter Impact on the Chart [#filter-impact-on-the-chart]
All filters in the Aging Chart perform two important functions:
1. **Control scope for statistics calculation** — determine which historical tasks to use for building percentiles and color zones
2. **Filter displayed current tasks** — which WIP tasks to show as dots on the chart
### Main Filters: [#main-filters]
* **Time frames**: Period for calculating historical statistics (e.g., last 3 months)
* **Quick filters**: Pre-configured board filters
* **Swimlanes**: Filter by specific swimlanes
* **Selected Columns**: Defines workflow columns that:
* Display on the chart (X-axis)
* Participate in accumulated time calculation
* Used for building statistics
* **Filtering mode**: Criteria for determining completed tasks
**Important**: Changing any filter recalculates all statistics and can significantly change color zones and percentile lines.
## What the Chart Says About Your Work [#what-the-chart-says-about-your-work]
### 1. Identifying Problems and Risks [#1-identifying-problems-and-risks]
**Look at tasks in red zones** — these are tasks executing slower than 95% of similar tasks from the past. Items in the upper part of the aging chart represent the highest risk to team reputation and customer satisfaction.
**Pay attention to task clusters** in one column — this may indicate:
* Process bottleneck
* Shortage of people or skills at this stage
* Technical problems or dependencies
**Tasks above the 85th line** already require attention, don't wait for them to reach the red zone.
### 2. Understanding Overall Process Health [#2-understanding-overall-process-health]
**Healthy process looks like:**
* Tasks evenly distributed across columns
* Most dots are in green and yellow zones
* Few tasks in red zones
**Problematic process:**
* Many tasks accumulated in one or two columns
* Many red dots (especially in initial columns)
* General "upward shift" of all tasks on the chart
### 3. Early Warning of Future Problems [#3-early-warning-of-future-problems]
The aging chart works as an early warning radar. Problems you see today in initial columns will become big problems tomorrow in final columns.
**What to watch for:**
* **Tasks in red zone in initial columns** — they will definitely cause problems later
* **Growing number of tasks above 85th line** — trend toward deterioration
* **Repeating patterns** — same problems every week
### 4. Data-Driven Decision Making [#4-data-driven-decision-making]
**Questions the chart answers:**
* How much work can we take on simultaneously?
* Which column regularly has problems?
* Are our process improvements helping?
* Which tasks need escalation right now?
**Possible approaches to problem solving:**
* **When there are too many tasks in red zones** some teams reconsider WIP limits
* **For persistent problems in specific columns** consider resource reallocation or process adjustments
* **When tasks regularly "age" in certain columns** it's worth analyzing and possibly adapting the workflow
## How to Use the Chart in Work [#how-to-use-the-chart-in-work]
### 1. Daily Standups Usage Options [#1-daily-standups-usage-options]
**Aging Chart can be useful for structuring discussions:**
* Teams often start by reviewing tasks in red zones to identify priorities
* Tasks above the 85th line may signal the need for additional support
* New tasks in yellow zones are worth noting for monitoring
Many teams find it helpful to use the aging chart as a starting point for conversations about flow blockers.
### 2. Percentile Configuration [#2-percentile-configuration]
Percentile selection depends on team needs:
* **Simple analysis**: 50% and 85% lines
* **Detailed analysis**: all five lines (30%, 50%, 70%, 85%, 95%)
* **Historical period**: adjust to team planning cycles
### 3. Connection with Other Reports [#3-connection-with-other-reports]
**Use together for complete picture:**
* **CFD (Cumulative Flow)** — shows task accumulation, Aging Chart — what to do with them
* **Lead Time** — shows how long completed tasks usually take
* **Throughput** — how many tasks we complete, Aging Chart — are we taking too much work
### 4. Examples of Working with Problematic Tasks [#4-examples-of-working-with-problematic-tasks]
**Approaches to working with tasks in red zones:**
Teams use different strategies for working with problematic tasks:
1. Analyzing tasks by clicking on dots to open in Jira
2. Identifying blockers and dependencies that hinder progress
3. Assigning responsible parties for resolving identified issues
4. Setting timeframes for unblocking
**Process improvement options:**
* When problems recur in one column, consider analyzing processes at that stage
* When red tasks appear frequently, teams may consider adjusting WIP limits
The specific approach depends on team culture and workflow characteristics.
## Practical Recommendations [#practical-recommendations]
### Basic Usage Principles [#basic-usage-principles]
* Focus on tasks in red zones as risk indicators
* Look for systemic causes of problems
* Use the chart for trend identification, not one-time assessments
* Regularly review percentile settings for team needs
### Data Quality [#data-quality]
The aging chart is only as good as your data. Ensure columns reflect real work stages, not formal statuses.
**Check:**
* Are all important work stages represented by columns?
* Do you move tasks to the next column as soon as work begins?
* Do filters match your actual work scope?
## Conclusion [#conclusion]
The Aging Chart is not just a pretty picture, but a practical tool for managing delivery risks. Practice shows that teams regularly using the aging chart significantly more often meet their commitments on time.
You can start with simple steps: introduce your team to the chart, try discussing problematic tasks at standups, strive to make data-driven decisions. Gradually teams learn to notice problems before they become critical, helping customers receive results more predictably and on time.
# Control Chart Report (https://jirametrics.pro/en/docs/reports/control-chart-report)
> **Premium.** The Control Chart report is available on the paid plan.
## Overview [#overview]
The Control Chart is a scatter plot in which **each dot is one completed task**. The horizontal axis shows the completion date, the vertical axis shows its completion time. The report shows how completion time is distributed over time, helps notice **outliers** (abnormally long tasks) and understand whether the process is stable or tasks are starting to take longer.
## Chart Structure [#chart-structure]

* **X-axis**: Task completion date.
* **Y-axis**: Task completion time in the selected units — days, weeks, or months (depends on the Resolution setting). Counted from 0.
* **Dots**: Each dot is a separate task. Hover the cursor to see the task key and the exact time; clicking opens the [Task Flow](/en/docs/reports/task-flow) dialog.
## Percentile Lines [#percentile-lines]
Three dashed horizontal reference lines are drawn on top of the dots:
* **P50 (green)** — the median: half of the tasks are completed faster than this time.
* **P85 (yellow)** — a reference point for SLA: 85% of tasks fit within this time.
* **P95 (red)** — 95% of tasks are faster; dots above this line are the "tail", candidates for analysis.
A line is shown only if its value is greater than 0. The same values are duplicated in the caption below the chart.
## How It Is Calculated [#how-it-is-calculated]
* **A dot's time** is taken precisely — milliseconds are divided by the length of the selected unit, without rounding.
* **The values of the P50/P85/P95 lines** are calculated differently — the same way as in the Lead Time report: from a histogram of whole-number values, using the cumulative distribution method without interpolation. That is why a line may run slightly above the "cloud" of dots — this is expected: the dots are precise, while the lines are aligned to whole "bins".
* The lines are calculated **from exactly those tasks that are visible on the chart** (they have a completion date and a completion time greater than 0). The Total Issues number in the metrics block is the very base of the line calculation, so the values can be verified manually.
## Metrics of This Report [#metrics-of-this-report]
Below the chart there is a metrics block:
* **Total Issues** — the number of tasks on the chart (the number of dots). Highlighted.
* **P50 / P85 / P95** — the values of the same completion time percentiles.
The trend versus the previous period is **not shown** in this report. For more about metrics blocks, see the [Metrics and Trends](/en/docs/core-concepts/metrics-and-trends) section.
## Interactive Elements [#interactive-elements]
When hovering over a dot, a tooltip appears:
* **Task key**
* **Lead Time** — the exact completion time
* **Completed** — the completion date
* The "Click to view history" hint — clicking opens the task history
## Impact of Settings [#impact-of-settings]
* **Resolution** changes the unit of the Y-axis (days/weeks/months). The dots remain precise, while the percentile lines are aligned to whole units — with a large unit (weeks, months) they look more "stepped".
* **Selected columns, completion columns, filtering mode, date range, swimlanes, and quick filters** have the same effect as in other reports.
## Tabular Representation [#tabular-representation]
The **"Show as table"** toggle displays a list of tasks sorted by completion time in descending order. Rows lead to Jira or open the task history — convenient for analyzing the longest tasks.
## Special Cases [#special-cases]
If there is not a single task with a completion date and a completion time greater than 0, the report shows an empty state.
## Usage Recommendations [#usage-recommendations]
1. Pay attention to dots **above the P95 line** — these are the longest tasks, analyze them separately.
2. If the dots' completion times grow from left to right, the process is slowing down and it is worth finding the cause.
3. The vertical spread of the dots shows variability: the greater it is, the less predictable the process.
# Cumulative Flow Diagram (CFD) Report (https://jirametrics.pro/en/docs/reports/cumulative-flow-diagram-report)
## Overview [#overview]
The Cumulative Flow Diagram (CFD) is a powerful visual tool for analyzing the flow of tasks through various stages of your workflow. It allows you to assess team performance, identify bottlenecks, and forecast completion times.
## Chart Structure [#chart-structure]
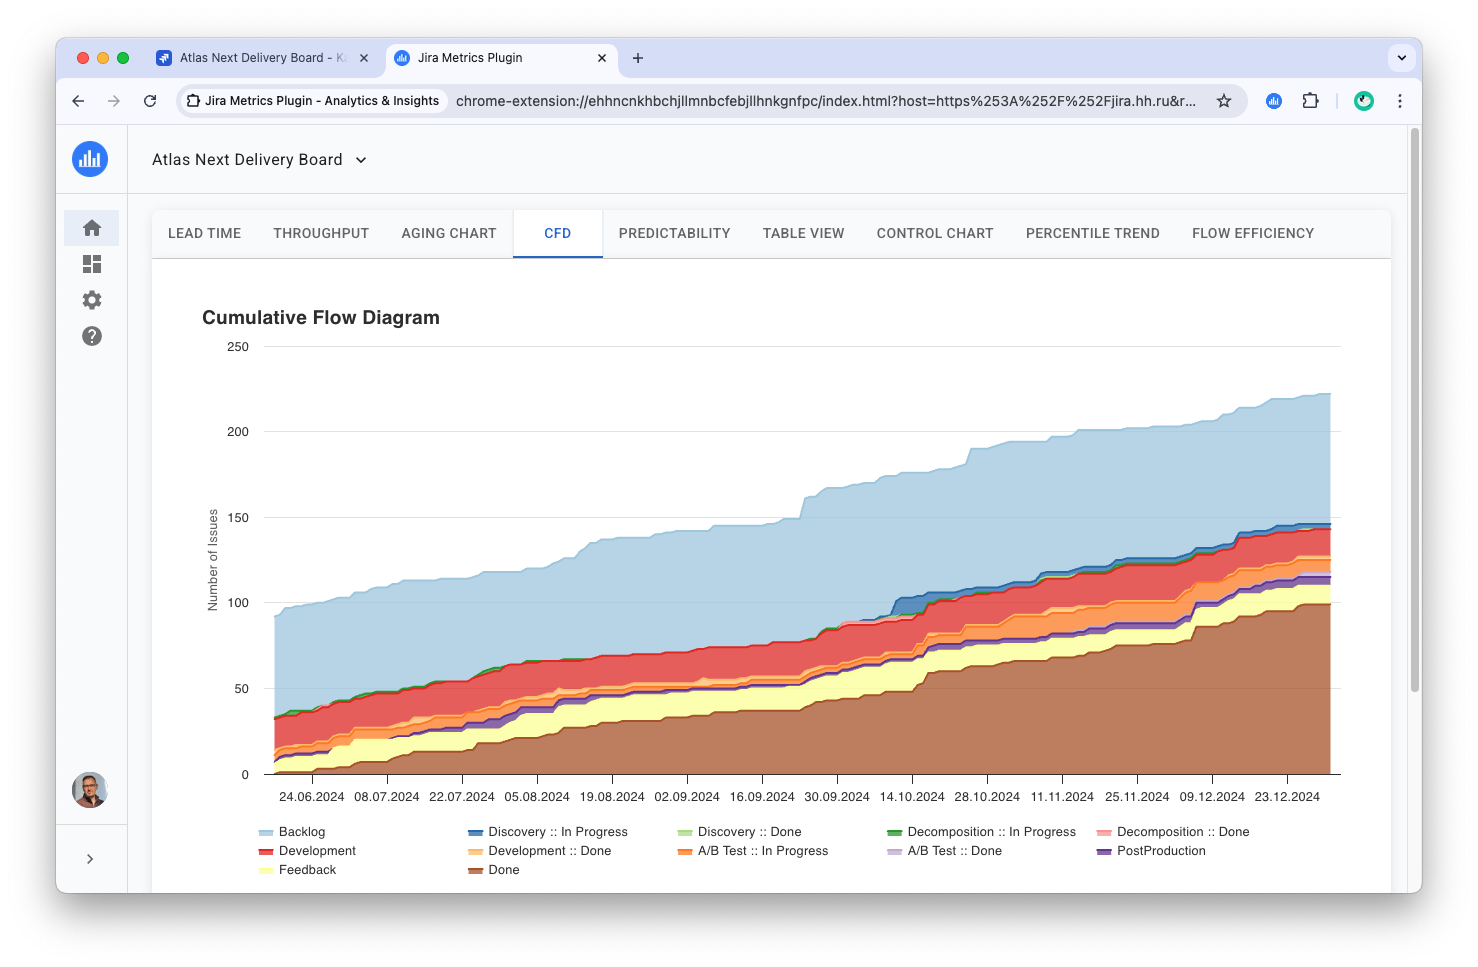
* **X-axis**: Timeline (dates)
* **Y-axis**: Number of tasks
* **Colored areas**: Each color represents a separate status or work stage, corresponding to the columns of your Kanban board
## Interpreting the Diagram [#interpreting-the-diagram]
1. **Band width**: Shows the average time tasks spend in a certain status. A wide band may indicate a potential bottleneck.
2. **Slope of lines**: A steep rise in a line indicates a rapid increase in the number of tasks in that status, while flat sections indicate stability or stagnation.
3. **Gaps and overlaps**: Gaps between areas may indicate loss of work, while overlaps may indicate parallel work or rework.
4. **Overall trend**: The overall slope of the top line shows the rate at which new tasks are entering the system.
## Interactive Elements [#interactive-elements]
1. **Tooltips**: When hovering over a specific point on the diagram, a tooltip appears containing:
* Date
* Number of tasks in each status
* Total number of tasks on that date
2. **Daily details**: Clicking on a specific day displays detailed information at the bottom of the page:
* List of tasks divided by status
* Task numbers are presented as clickable links leading to the corresponding task page in Jira
3. **Display management**: Clicking on a legend element hides or shows the corresponding column. **Cmd/Ctrl + click** leaves only the one selected column on the diagram (another Cmd/Ctrl + click brings them all back) — convenient for focusing on a single stage.
## Report Configuration [#report-configuration]
The main filters (period, swimlanes, quick filters) are located in the **common filter panel** above the report, not below the diagram. For more details, see the [Data Sampling and Filtering](/en/docs/core-concepts/data-sampling-and-filtering) section.
The diagram itself has a **"Show all colors"** toggle (in the card header, enabled by default). When it is turned off, columns that are not among the selected ones are shown muted (semi-transparent) — this makes it easier to highlight the stages you need without removing the rest completely.
## Usage Recommendations [#usage-recommendations]
1. **Trend analysis**: Regularly track changes in the shape and size of areas to identify long-term trends.
2. **Bottleneck identification**: Pay attention to expanding areas that may indicate task accumulation in a certain status.
3. **Performance assessment**: Analyze the speed of task transitions from one status to another to evaluate process efficiency.
4. **Forecasting**: Use the slope of lines to predict completion times for future tasks.
5. **Detailed analysis**: Use the day-click function for in-depth analysis of the project state on a specific date.
6. **Focus on specific stages**: Use the legend to hide or display certain columns to concentrate on specific aspects of the process.
## Conclusion [#conclusion]
The Cumulative Flow Diagram provides a comprehensive view of work flow in your project. Regular CFD analysis will help you optimize processes, improve predictability of timelines, and increase overall team efficiency. The flexibility of configuration and interactive elements allow you to adapt the analysis to the specifics of your workflow.
# Flow Efficiency Report (https://jirametrics.pro/en/docs/reports/flow-efficiency-report)
> **Premium.** The Flow Efficiency report is available on the paid plan.
## Overview [#overview]
Flow Efficiency shows **what share of a task's completion time is active work and what share is waiting**. The formula:
```
Flow Efficiency, % = Active Time / Total Time × 100
```
The higher the efficiency, the less tasks "hang" in queues and waiting between stages. It often turns out that most of the time a task is simply waiting rather than being processed — this report makes such a picture visible.
For the report to work, you need to specify **which columns are considered "active"** (see below).
## Chart Structure [#chart-structure]

* **X-axis**: Periods (week, month, quarter, or year).
* **Y-axis**: Efficiency as a percentage (from 0 to 100).
* **Bars or a line** (your choice) — the efficiency for each period.
* **The "Accumulated Average" line** — the cumulative average of efficiency on a running total basis.
## How It Is Calculated [#how-it-is-calculated]
For each task completed in a period:
* **Active time** — the sum of time spent in the columns marked as "active".
* **Total time** — the sum of time across all selected columns.
* **Period efficiency** = (total active time / total time) × 100.
The "Accumulated Average" line is a **simple average** of the period efficiencies, accumulated from left to right.
## Metrics of This Report [#metrics-of-this-report]
Below the chart there is a metrics block:
* **Flow Efficiency** — the overall efficiency, calculated as a **weighted** value (total active time ÷ total time across all tasks). Highlighted. Note: this weighted number may differ slightly from the last point of the "Accumulated Average" line, because the line is a simple average while the card is weighted.
* **Avg Wait Time** — the average wait time per task in days: (total − active) / number of tasks.
* **Avg Active Time** — the average active time per task in days.
* **Completed Items** — the number of completed tasks.
The trend versus the previous period is **not shown** in this report. For more about metrics blocks, see the [Metrics and Trends](/en/docs/core-concepts/metrics-and-trends) section.
## Configuring Active Columns [#configuring-active-columns]
Using the **active columns** dropdown, mark the statuses where real work happens (for example, "In Progress", "Review"), and **do not mark** queues and waiting (for example, "Backlog", "Waiting").
Until active columns are selected, the report shows a **configuration screen** instead of the chart — efficiency cannot be calculated without them.
## Interactive Elements [#interactive-elements]
When hovering over a bar/point, a tooltip appears:
* **Period**
* **Efficiency** — the efficiency as a percentage
* **Active Time** — the active time (days)
* **Total Time** — the total time (days)
* **Tasks** — the number of tasks
* Click — open the period's tasks in Jira
## Impact of Settings [#impact-of-settings]
* **Active columns** — which statuses are considered work (see above).
* **Period type** — week, month (default), quarter, or year.
* **Chart type** — bars or line.
* Plus the global filters: selected columns, filtering mode, date range, swimlanes.
## Usage Recommendations [#usage-recommendations]
1. Low flow efficiency is normal for many teams; its **dynamics** matter more than the absolute value.
2. Watch **Avg Wait Time**: if the wait time is growing, tasks are idling longer and longer between stages.
3. Choose the active columns carefully — the result depends on this directly. If you mark waiting as active work, the efficiency will be overstated.
# Lead Time Report (https://jirametrics.pro/en/docs/reports/lead-time-report)
## Overview [#overview]
The Lead Time report is a distribution histogram that displays task completion times. This report is ideal for general assessment of workflow durations and identifying different types of tasks.
## Histogram Structure [#histogram-structure]
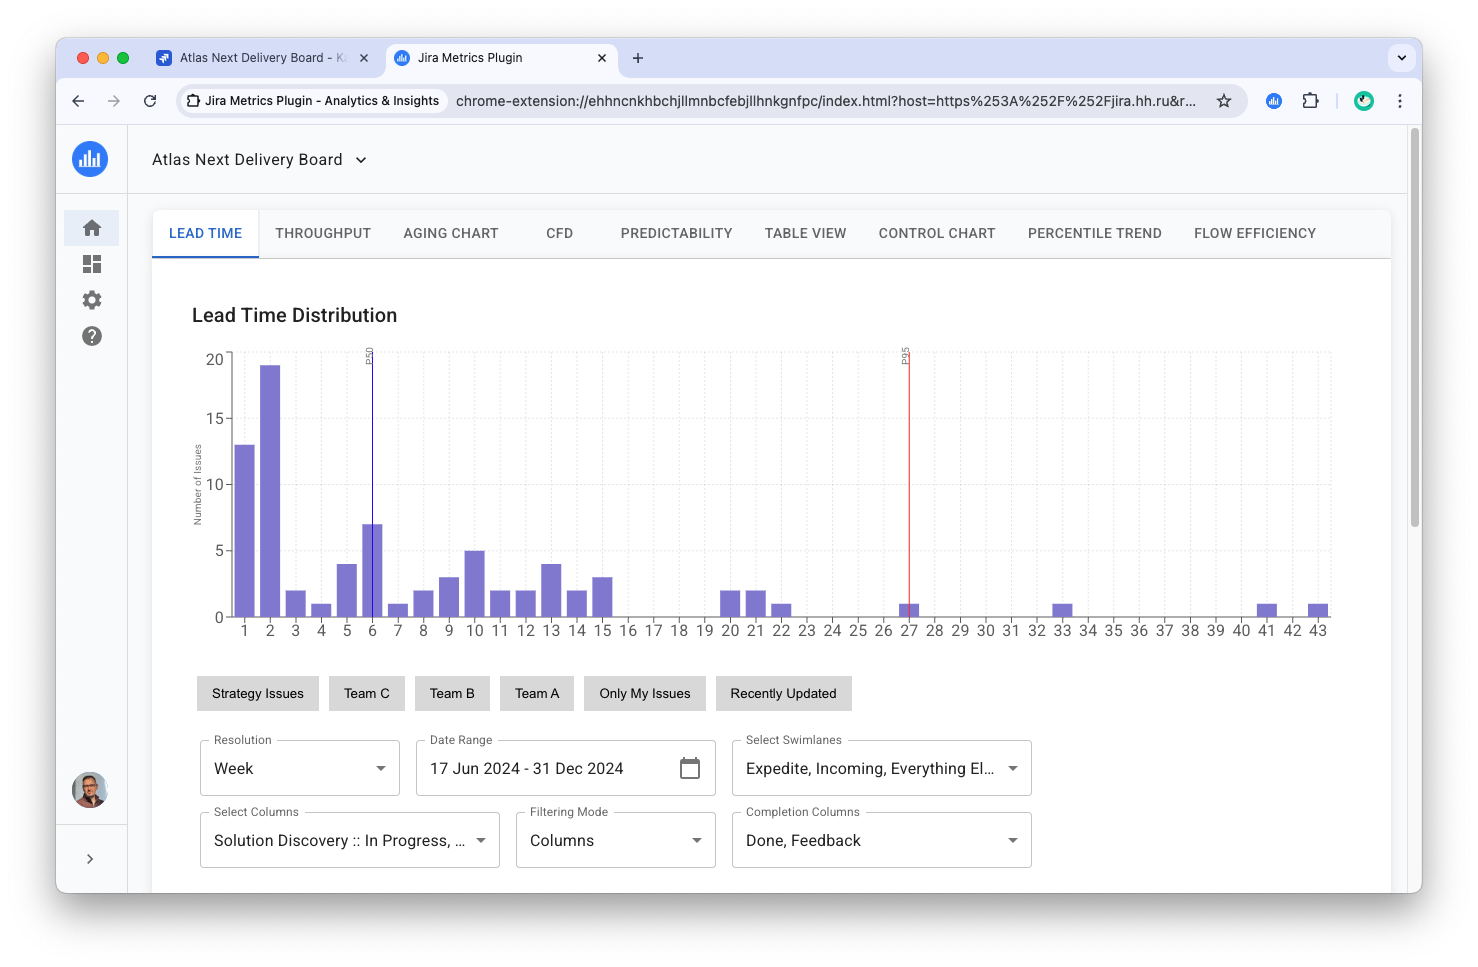
* **X-axis**: Task completion time (in days, weeks, or months)
* **Y-axis**: Number of tasks completed in the specified time
The graph marks three vertical reference lines:
* **Green line (P50)**: 50th percentile (median). Shows the time in which half of all tasks are completed.
* **Yellow line (P85)**: 85th percentile. A reference point for SLAs — 85% of tasks fit within this time.
* **Red line (P95)**: 95th percentile. Marks the time in which the vast majority of tasks are completed. Tasks to the right of this line are considered "tails" or anomalies and require separate analysis.
Each line has a label with its percentile and value (for example, `85%: 12 days`).
## Interactive Elements [#interactive-elements]
When hovering over a histogram bar, a tooltip appears with the following information:
* **Lead Time**: Completion time for this group of tasks
* **Tasks**: Number of tasks in this group
* **Percentile**: Percentage of tasks that are completed in this time or faster
## Lead Time Calculation [#lead-time-calculation]
Lead Time is calculated as the sum of time a task spent in all selected columns. It's important to note:
1. The selection of columns in the "Columns" filter determines which tasks are included in the sample and what time is considered in calculations.
2. You can select multiple columns, not necessarily sequential on the board.
3. Time in the last column on the board (usually "Done") is not included in the total Lead Time.
4. The report considers all tasks for the selected period, regardless of their status (closed or not).
## Impact of Filtering Mode [#impact-of-filtering-mode]
The filtering mode ("Activity" or "Completion") affects the set of displayed tasks:
* **Activity**: Considers all tasks active in selected columns during the specified period.
* **Completion**: Focuses on tasks that have passed through the specified completion columns (Completion Columns).
For more details on filtering modes, see the [Filtering Modes](/en/docs/core-concepts/filtering-modes) section.
## Metrics Block [#metrics-block]
Below the histogram is a metrics block with the key numbers:
* **Total Issues**: the number of tasks on the chart (the sum across the histogram bars). Highlighted. Tasks with a completion time of 0 days are not included here — they are counted separately (see the "Excluded Tasks" section).
* **P50**: 50th percentile (median) in the selected units — days, weeks, or months.
* **P85**: 85th percentile.
* **P95**: 95th percentile.
The P50/P85/P95 values match the lines of the same name on the histogram. A trend versus the previous period is not shown in this report. For more details on metrics blocks, see the [Metrics and Trends](/en/docs/core-concepts/metrics-and-trends) section.
### How Percentiles Are Calculated [#how-percentiles-are-calculated]
**Definition**: Pn is the completion time value at which n% of tasks have time ≤ this value.
**Calculation Method**: Discrete method with cumulative distribution
1. Tasks are grouped by completion time
2. Cumulative sum is calculated
3. Percentile = first value where (accumulated count / total count) × 100 ≥ target percentile
**Example of 50th percentile (median) calculation**:
* 2 tasks at 1 day (33.3% accumulated)
* 3 tasks at 2 days (83.3% accumulated)
* 1 task at 5 days (100% accumulated)
Since 83.3% ≥ 50%, **P50 = 2 days**
#### Why This Method Is Used [#why-this-method-is-used]
* **Data Consistency**: Lead Time values are rounded to whole units (days/weeks/months), and histogram consists of discrete "bins". Discrete nearest-rank percentile without interpolation correctly reflects this data nature.
* **Interpretability**: Percentiles return actual values on X-axis, matching P50/P95 lines on the graph and understandable to business.
* **Outlier Resistance**: Median and high percentiles are less sensitive to individual anomalies than the mean.
* **Report Consistency**: Method is consistent with tables/widgets; adding "empty" bins (count=0) doesn't affect results.
#### Excluded Tasks [#excluded-tasks]
Tasks with completion time of 0 days are excluded from calculations but displayed as a separate counter.
## Tabular Data Representation [#tabular-data-representation]
The "Show as table" option allows you to display all tasks in a table format, where each row corresponds to a histogram bar. The table is sorted by Lead Time from highest to lowest, which is convenient for analyzing tasks with the longest completion times.
## Usage Recommendations [#usage-recommendations]
1. Use quick filters for more precise analysis. For example:
* To analyze only closed tasks: `Resolution != Unresolved`
* To analyze tasks for a specific period: `Resolved >= $Start_date AND Resolved < $End_date`
2. Pay attention to tasks falling into the "tail" of the distribution (after the 95th percentile). They may indicate process problems or require special attention.
3. Regularly analyze changes in Lead Time distribution to track the effectiveness of implemented improvements.
4. Use the tabular representation when preparing for delivery process reviews, focusing on tasks with the longest completion times.
# Percentile Trend Report (https://jirametrics.pro/en/docs/reports/percentile-trend-report)
> **Premium.** The Percentile Trend report is available on the paid plan.
## Overview [#overview]
The Percentile Trend is a line chart showing how **the selected completion time percentile** (the 85th by default) changes from period to period: month by month, quarter by quarter, or year by year. The report answers the question: is the process getting faster or slower over time?
For example, the line for the 85th percentile shows how many days 85% of tasks fit within in each period. If the line goes down, tasks have started to be completed faster.
## Chart Structure [#chart-structure]

* **X-axis**: Periods (months, quarters, or years — depends on the Period setting).
* **Y-axis**: Time in **days**. The axis is always in days, regardless of the global Resolution setting.
* **Line**: The value of the selected percentile in each period. You can enable value labels directly on the points.
## How It Is Calculated [#how-it-is-calculated]
For each period:
1. Tasks completed in this period are taken.
2. Their completion time is converted into whole days (rounded up).
3. A distribution is built, from which the selected percentile is taken (the cumulative distribution method, as in the Lead Time report).
4. The value is rounded to whole days.
## Metrics of This Report [#metrics-of-this-report]
Below the chart there is a metrics block:
* **Average P85** (or another selected percentile) — the average percentile value across all periods (days). Highlighted.
* **Minimum** — the smallest percentile value among the periods (days).
* **Maximum** — the largest percentile value among the periods (days).
* **Trend** — the direction of the dynamics. The value in the **first** period is compared with the value in the **last** one: a change of more than 5% in either direction → `Increasing` / `Decreasing`, otherwise `Stable`. A decrease is an improvement (green ↓), an increase is a deterioration (red ↑).
This is a trend "within the selected range", not a comparison with a separate previous period. For more details, see the [Metrics and Trends](/en/docs/core-concepts/metrics-and-trends) section.
## Interactive Elements [#interactive-elements]
When hovering over a point, a tooltip appears:
* **Period**
* **Tasks** — the number of tasks in the period
* **Nth percentile** — the value in days
* **Average** — the average time in the period (days)
* Click — open this period's tasks in Jira
## Impact of Settings [#impact-of-settings]
* **Period** — the period type: month, quarter (default), or year.
* **Percentile** — which percentile to plot: 50, 70, 80, 85 (default), 90, or 95.
* **Showing values on points** — enable/disable the labels.
* **Filtering mode.** The report is built correctly in **Completion** mode. In **Activity** mode a warning is shown — switch to Completion.
* The global **Resolution setting does not affect this report** — the values are always in days.
## Special Cases [#special-cases]
* If there are no tasks in any period, the report is empty.
* At least two periods with a value are required to calculate the trend — if there is less data, the Trend card shows `N/A`.
* Periods without completed tasks are shown as a **break in the line**, not as zero: "0 days" would mean instant completion rather than the absence of data.
## Usage Recommendations [#usage-recommendations]
1. Use the report to track the effect of process improvements over a long horizon — compare P85 quarter over quarter.
2. A rising line is a signal that the process is becoming less predictable and slow.
3. Look not only at the average, but also at the spread between Minimum and Maximum — a large spread means instability from period to period.
# Predictability Chart Report (https://jirametrics.pro/en/docs/reports/predictability-report)
## Overview [#overview]
The Predictability Chart is a metric proposed by Kanban University to measure the stability and predictability of a team's workflow. This report helps assess how reliably a team can forecast task completion times.
## Building the Predictability Chart [#building-the-predictability-chart]
### 1. Data Collection [#1-data-collection]
* Collect lead time data for each task over a specific period.
* It's important to ensure data accuracy and cover a sufficient time range for statistical significance.
### 2. Percentile Calculation [#2-percentile-calculation]
* **50th percentile (median)**: The time value below which 50% of tasks are completed.
* **98th percentile**: The time value below which 98% of tasks are completed.
### 3. Calculating the 98% / 50% Ratio [#3-calculating-the-98--50-ratio]
* Ratio = 98th percentile / 50th percentile
* This ratio shows the degree of variability in the process. A lower value means a more predictable process.
### 4. Plotting the Graph [#4-plotting-the-graph]
* **X-axis**: Calendar months. The graph is always plotted by months, regardless of the Resolution setting.
* **Y-axis**: The 98% / 50% ratio for each month (the axis label is "Ratio to median (98% / 50%)")
* Points on the graph are connected with a line; a separate dashed line shows the overall trend. The trend line is only plotted when there are **three months of data or more** — a trend cannot be determined from one or two points
## Chart Structure [#chart-structure]
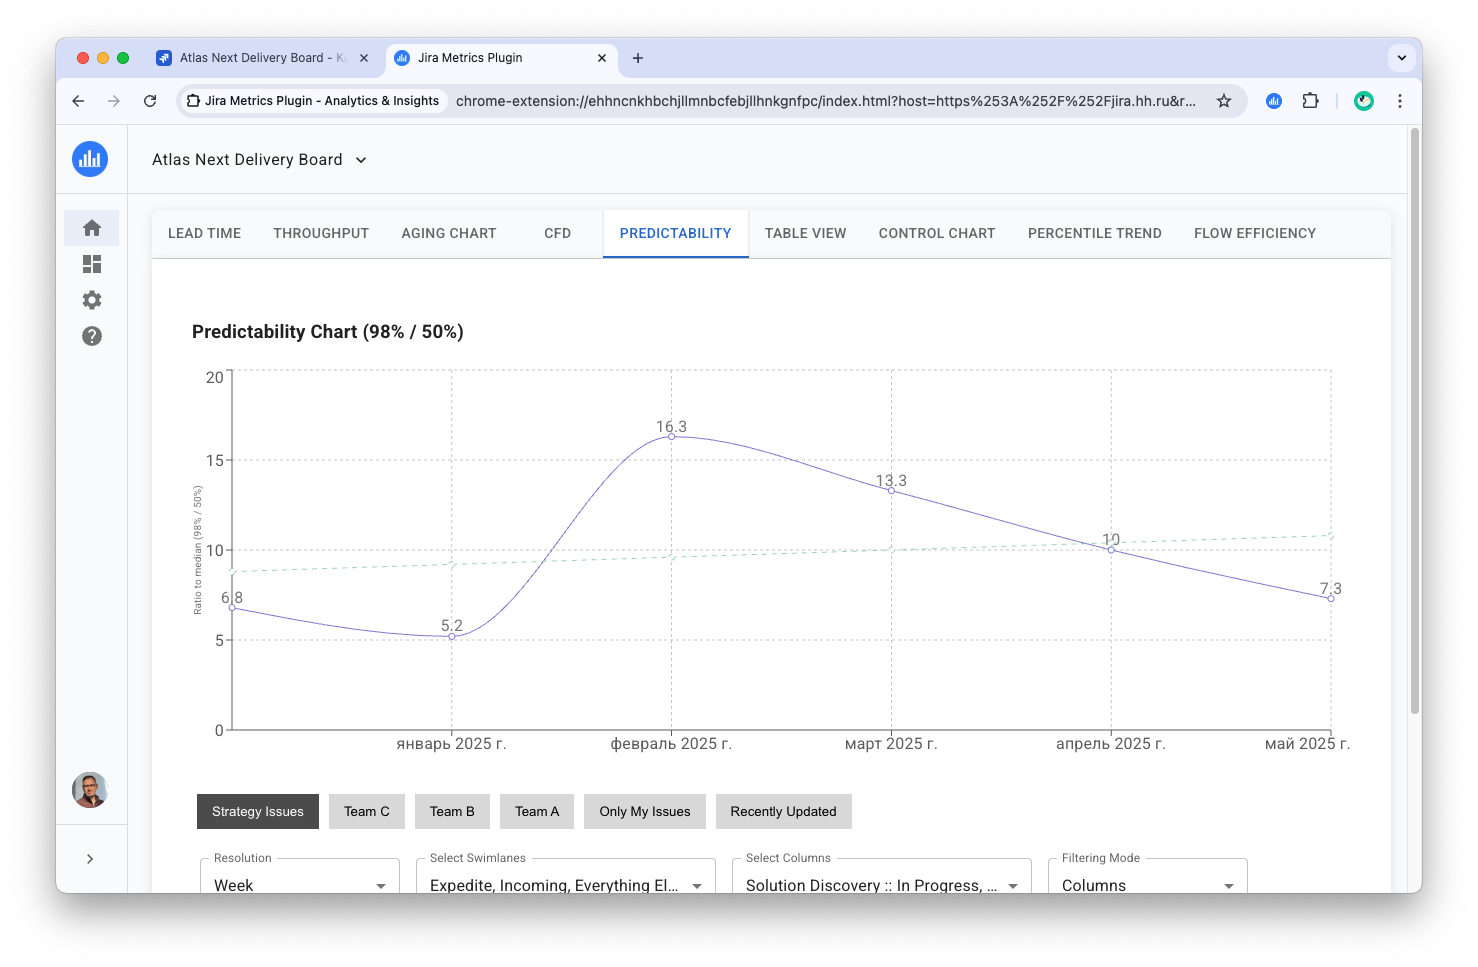
The chart shows a line representing the change in the 98% / 50% ratio over time. The values on the graph reflect the degree of process predictability.
## Interpreting Values [#interpreting-values]
The main principle: **the lower the ratio, the more predictable the process.**
* **Value close to 1**: very high predictability — the "tail" of long tasks barely differs from the median.
* **The higher the value** — the greater the spread: some tasks take much longer than typical ones, and the process is less predictable.
Reference points for interpretation:
* **up to 3** — predictable flow: the "tail" of long tasks is close to typical tasks;
* **from 3 to 5.6** — moderate variability;
* **above 5.6** — a fat tail. The 5.6 reference point is not arbitrary: it is the P98/P50 ratio of a "whatever happens" process (pure randomness with no flow management). Higher values mean the tail is heavier than random — the process requires attention.
On the graph this corresponds to the dashed **Fat-tail threshold (5.6)** line. And most importantly: focus primarily on the **dynamics** (whether the ratio is decreasing or growing), not on a single absolute value.
## Trend Analysis [#trend-analysis]
* **Decreasing ratio over time**: Indicates process improvement and increased stability.
* **Increasing ratio**: May signal possible problems or changes in the process that require attention.
* **Stable line**: Indicates an unchanged, but not improving process.
## Report Configuration [#report-configuration]
All filters (period, swimlanes, columns, filtering mode, completion columns, Resolution) are located in the **common filter panel** above the report. For more details, see the [Data Sampling and Filtering](/en/docs/core-concepts/data-sampling-and-filtering) and [Filtering Modes](/en/docs/core-concepts/filtering-modes) sections.
The report always calculates completion time **in days** — the Resolution setting does not affect it. The graph is always broken down by calendar months.
## Practical Usage Tips [#practical-usage-tips]
1. **Regular monitoring**: Update and analyze the chart regularly to detect deviations in a timely manner.
2. **Finding causes of variability**: For high ratios, analyze tasks with long completion times to identify causes of delays.
3. **Implementing improvements**: Use the data obtained to optimize processes, eliminate bottlenecks, and increase efficiency.
4. **Comprehensive analysis**: Consider the Predictability Chart in combination with other metrics, such as Lead Time and Throughput, for a full analysis.
5. **Context consideration**: Take into account the specifics of the project and team when interpreting values.
## Metric Limitations [#metric-limitations]
* Does not account for task size or complexity.
* May be sensitive to outliers, especially with a small number of tasks.
* Does not reflect the reasons for changes in predictability.
## Conclusion [#conclusion]
The Predictability Chart is a valuable tool for assessing the stability and predictability of the development process. Regular analysis of this metric will help you identify areas for improvement, optimize work processes, and increase team efficiency.
# Task Flow (https://jirametrics.pro/en/docs/reports/task-flow)
## Overview [#overview]
**Task Flow** is a dialog that breaks down a single task's completion time across the board columns. It answers three questions:
1. **Where did the time go?** Which stage of the process took the most time for this particular task.
2. **Can the number be trusted?** If part of the task's history had to be reconstructed, the dialog honestly warns that the Lead Time is approximate.
3. **How do I tell the team about it?** One button copies a ready-made summary with a link to the task — convenient to paste into a retrospective document or a chat.
The dialog is especially useful for investigating "outliers" — tasks that took abnormally long. Instead of manually scrolling through the task history in Jira, in a few seconds you see which stage it got stuck in and whether it moved backward on the board.
{/* SCREENSHOT: общий вид диалога «Поток задачи» — шапка с ключом задачи, полоса FlowBar, строка диагноза, таблица «Путь по колонкам» */}
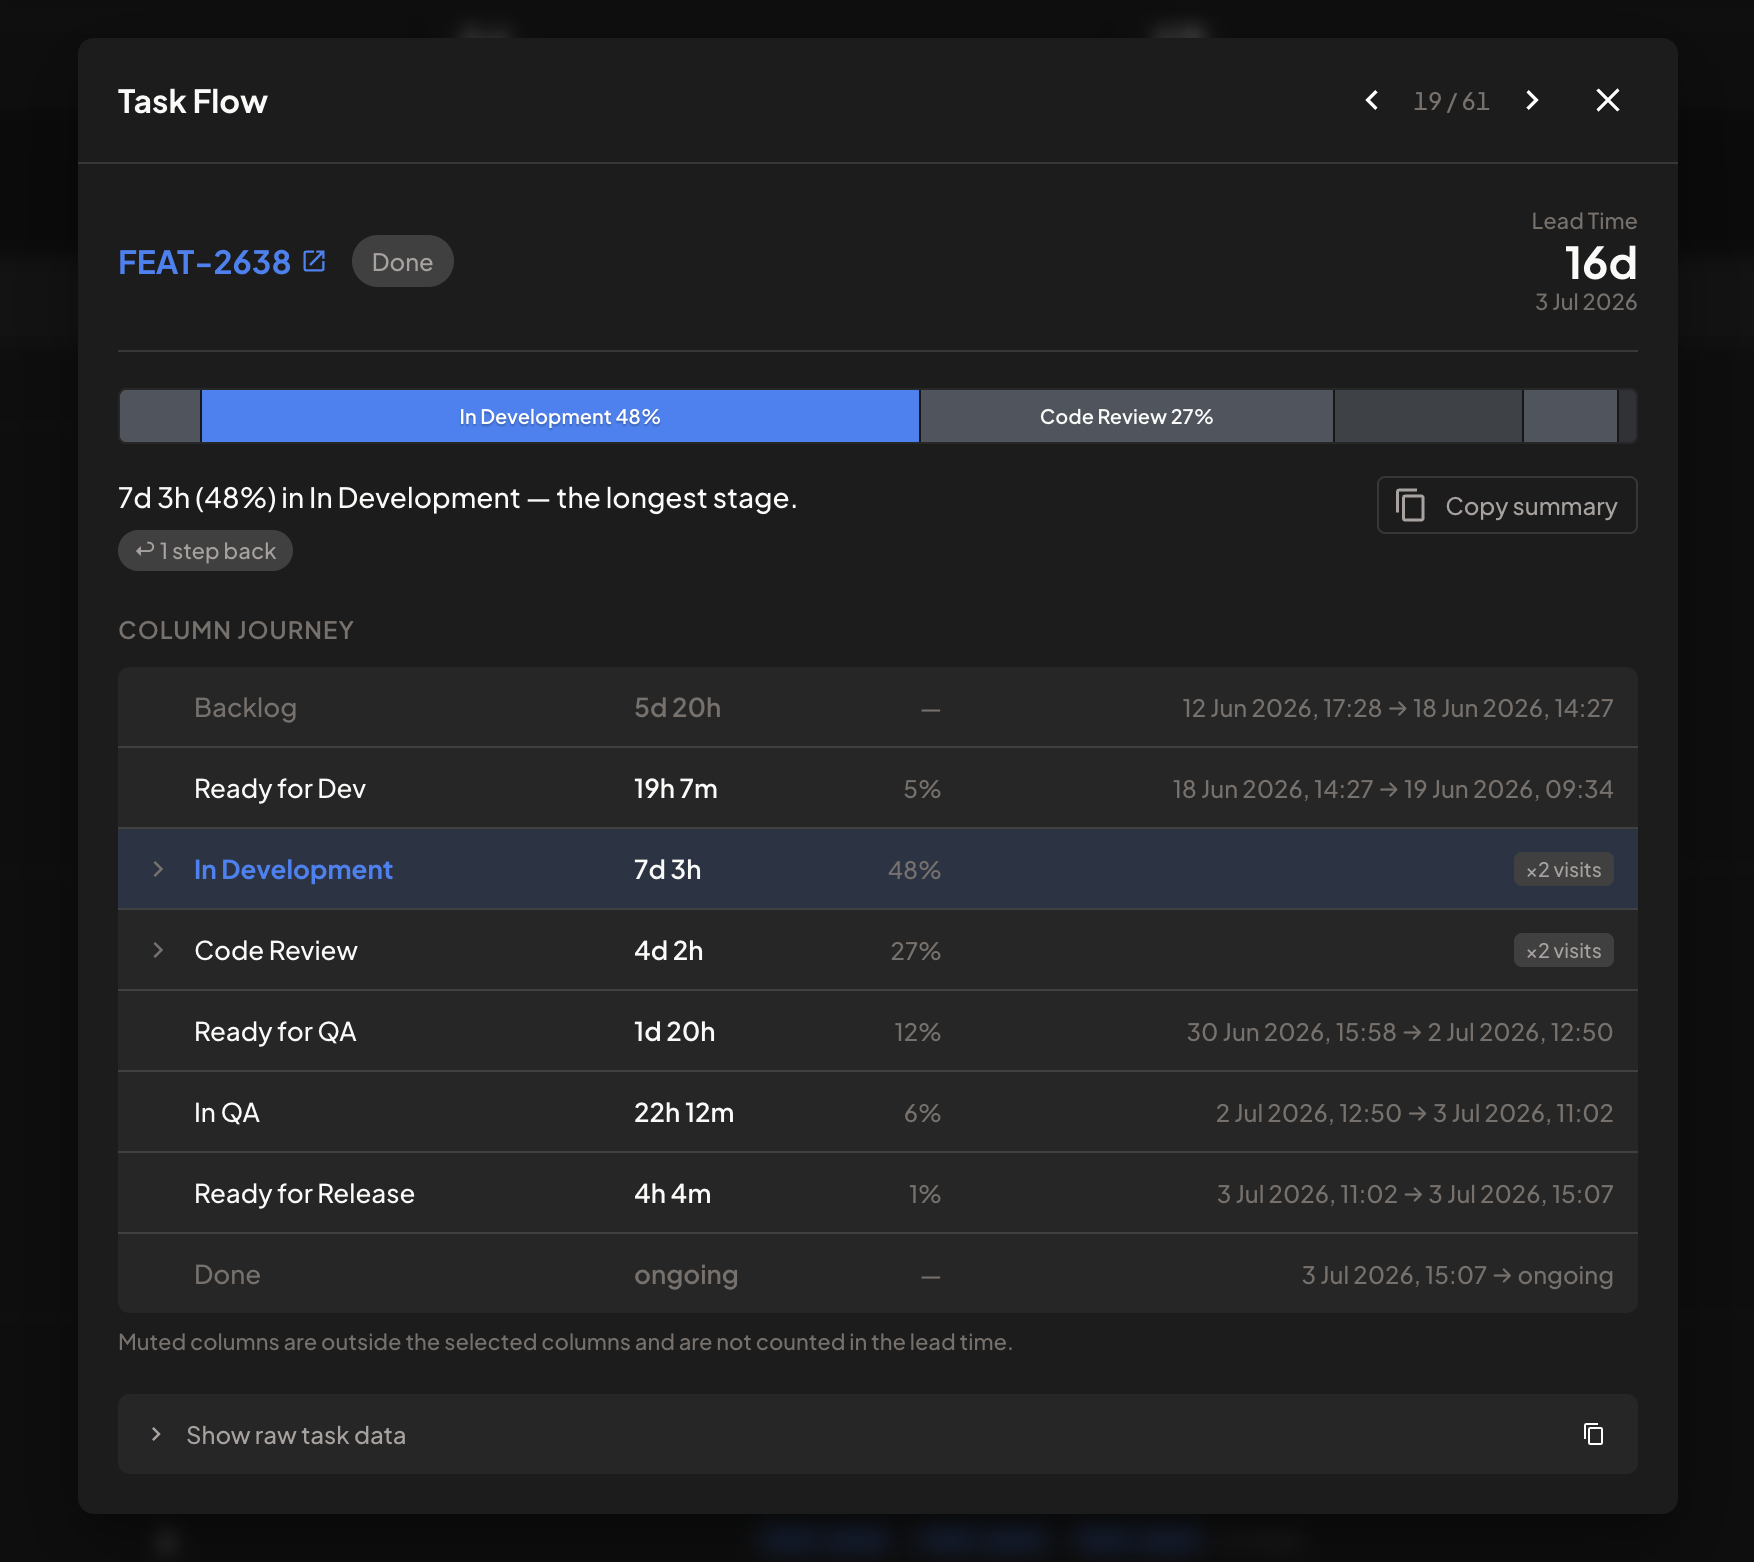
## How to Open the Dialog [#how-to-open-the-dialog]
Task Flow opens by clicking a task in almost any report:
* **Control Chart** — click a dot on the chart or a task key in the table below the chart (also works in the Control Chart dashboard widget).
* **Aging Chart** — click a task dot on the aging diagram.
* **Tasks Table** — click a task ID in the table.
* **Lead Time** — click a task in the report's table view, and also in the excluded tasks list.
* **Throughput Chart** — click a task key "pill" in the period's task list.
All the data for the dialog is already loaded with the report — no extra Jira requests are made, the dialog opens instantly.
## What the Dialog Consists Of [#what-the-dialog-consists-of]
### Task Header [#task-header]
* **Task key** is a link: clicking it opens the task in Jira in a new tab.
* **Current column** — a badge with the column the task is in right now.
* **Lead Time** — the big number on the right: the task's total completion time. It is calculated and rounded the same way as in reports, so "150d" here matches "150 days" in the Control Chart table. Below it is the completion date, if the task is done.
### Time Distribution Strip (FlowBar) [#time-distribution-strip-flowbar]
The full-width horizontal strip is the main visualization. Each segment is a board column (left to right in board order), and the segment width is the share of time the task spent in that column.
* **One column is highlighted in blue** — the one that took the most time. The rest are colored neutrally so your eye lands on what matters immediately.
* Segments shorter than 3% collapse into a single **"Other (N)"** segment to keep the strip readable.
* Hatched areas mark parts reconstructed from incomplete data (see "Trusting the Data").
* Hovering over a segment shows a tooltip: column name, duration, and percentage share.
{/* SCREENSHOT: крупный план FlowBar с выделенной доминирующей колонкой и тултипом на сегменте */}
### Diagnosis Line [#diagnosis-line]
Below the strip is a single sentence that states the main takeaway, for example:
> 12d (46%) in "Code Review" — the longest stage.
Qualifier chips may appear next to it:
* **"longest single stay N"** — if the time in the longest column accumulated over several visits, the chip shows the longest uninterrupted stay.
* **"↩ N steps back"** — how many times the task moved backward on the board (to a column further left). A backward move is an observed movement; it does not necessarily mean rework, but frequent backward moves are a reason to look closer at the process.
* **"⚠ approximate"** — a noticeable part of the timeline was reconstructed; treat exact figures with caution.
The **Copy summary** button next to the diagnosis line copies a ready-made summary to the clipboard: the task link, Lead Time, the longest stage, and the number of backward moves. The format is designed so the line can be pasted straight into a retro document.
### Column Journey [#column-journey]
A table of all the columns the task passed through, in board order:
* **Column name** — the longest one is highlighted in bold and color.
* **Time in column** — total across all visits (or "ongoing" if the task is currently in that column).
* **Share** — percentage of the tracked time.
* **"×N visits"** — if the task entered the column more than once. Such a row expands on click: inside, each visit is shown separately with entry and exit dates, duration, and the number of status changes (hovering over the status-changes badge reveals the chain of statuses).
* For columns with a single visit, the transition dates are shown right in the row: "entry date → exit date".
{/* SCREENSHOT: таблица «Путь по колонкам» с раскрытой колонкой с несколькими заходами */}
Muted rows are columns not included in the "Columns" filter selection: time in them is not counted toward the Lead Time. A footnote below the table reminds you of this as well.
### Navigating Between Tasks [#navigating-between-tasks]
If the dialog was opened from a task list (for example, from Tasks Table), arrows **←/→** and a "current / total" counter appear in the header. You can switch between tasks with the keyboard arrows — handy for quickly flipping through all long tasks in a row without closing the dialog.
### Raw Data [#raw-data]
At the bottom of the dialog is a collapsible **Show raw task data** block: the full task object in JSON format with a copy button. Useful when you need to check against the source data or attach it to a bug report.
## Trusting the Data [#trusting-the-data]
The transition history in Jira is not always complete: some tasks have gaps, and JMP reconstructs the missing parts of the timeline. The dialog does not hide this:
* reconstructed visits are marked with a **"reconstructed"** badge (and hatching on the FlowBar strip);
* if the reconstructed part is significant (more than 15% of the time, or the longest column itself is affected), a warning appears: *"⚠ Part of this timeline was reconstructed. Lead time is approximate"* — along with an "approximate" chip in the diagnosis line.
This is intentional: it is better to know a number is approximate than to make decisions based on a precise-looking but unreliable figure.
## How Percentages Are Calculated [#how-percentages-are-calculated]
Shares in the dialog are calculated from the **sum of time across the counted columns**, not from the calendar Lead Time. So the percentages always honestly add up to 100%, but due to rounding and reconstructed parts, the sum of durations may not literally match the big Lead Time number in the header.
Which columns count as "tracked" is determined by the "Columns" filter of the report the dialog was opened from — see [Data Sampling and Filtering](/en/docs/core-concepts/data-sampling-and-filtering) for details.
## Usage Scenarios [#usage-scenarios]
1. **Investigating an outlier.** A dot on the Control Chart sits far above the rest → click it → the dialog shows the task spent 80% of its time in "Waiting for deploy". A question for the retro formulated in ten seconds.
2. **Finding systematic delays.** Open Tasks Table, sort by Lead Time, and flip through the longest tasks with the arrow keys. If the same column dominates in all of them, it is no longer a coincidence — it is a property of the process.
3. **Checking for "ping-pong".** The backward-moves chip highlights tasks that traveled back and forth across the board — a common sign of unclear readiness criteria between stages.
4. **Material for the retro.** The "Copy summary" button produces one line per investigated task with a link and the numbers — a few such lines make a ready-made section of a retro document.
## Limitations [#limitations]
* The dialog shows the **facts of the task's movement** but does not interpret them: it deliberately does not split time into "active" and "waiting", does not compute flow efficiency, and does not label backward moves as "rework" — such conclusions are left to you and your context.
* When opened from the Aging Chart or from the Control Chart widget, all columns are treated as counted (no "in window / out of window" split by the "Columns" filter).
# Tasks Table Report (https://jirametrics.pro/en/docs/reports/task-table-report)
## Overview [#overview]
The Tasks Table provides a detailed tabular view of your project's tasks. This report allows you to analyze tasks that fall under selected filters, with the ability to sort and view the timeline of each task.
## Main Features [#main-features]
### Task Filtering [#task-filtering]
The same filters used in other reports are used to customize the task selection. You can learn more about working with filters in the [Data Sampling and Filtering](/en/docs/core-concepts/data-sampling-and-filtering) section.
### Time Display Format Configuration [#time-display-format-configuration]
You can choose a convenient time display format:
* **Default** — a compact view like "10d 8h" (the default format)
* **Hours** — hours
* **Days** — days
* **Weeks** — weeks
* **Timestamp** — the number of milliseconds
Examples of display for a task that took 10 days and 8 hours:
* Default: "10d 8h"
* Hours: "248.0h"
* Days: "10.3d"
* Weeks: "1.5w"
* Timestamp: "892800000" (milliseconds)
Changing the time format dynamically updates the data in the table.
### Data Export [#data-export]
The "Download CSV" button allows you to export all filtered tasks to a CSV file for further analysis.
It's important to note that in the CSV file, the numeric time formats ("hours", "days", and "weeks") are output as numerical values without units of measurement, rounded to one decimal place. For example:
* 248 (for hours)
* 10.3 (for days)
* 1.5 (for weeks)
The "Timestamp" format in CSV is preserved in the same form as in the table — in milliseconds.
### Sorting [#sorting]
Sorting is possible by any table column, including task ID, total lead time, and time in each column.
## Table Structure [#table-structure]
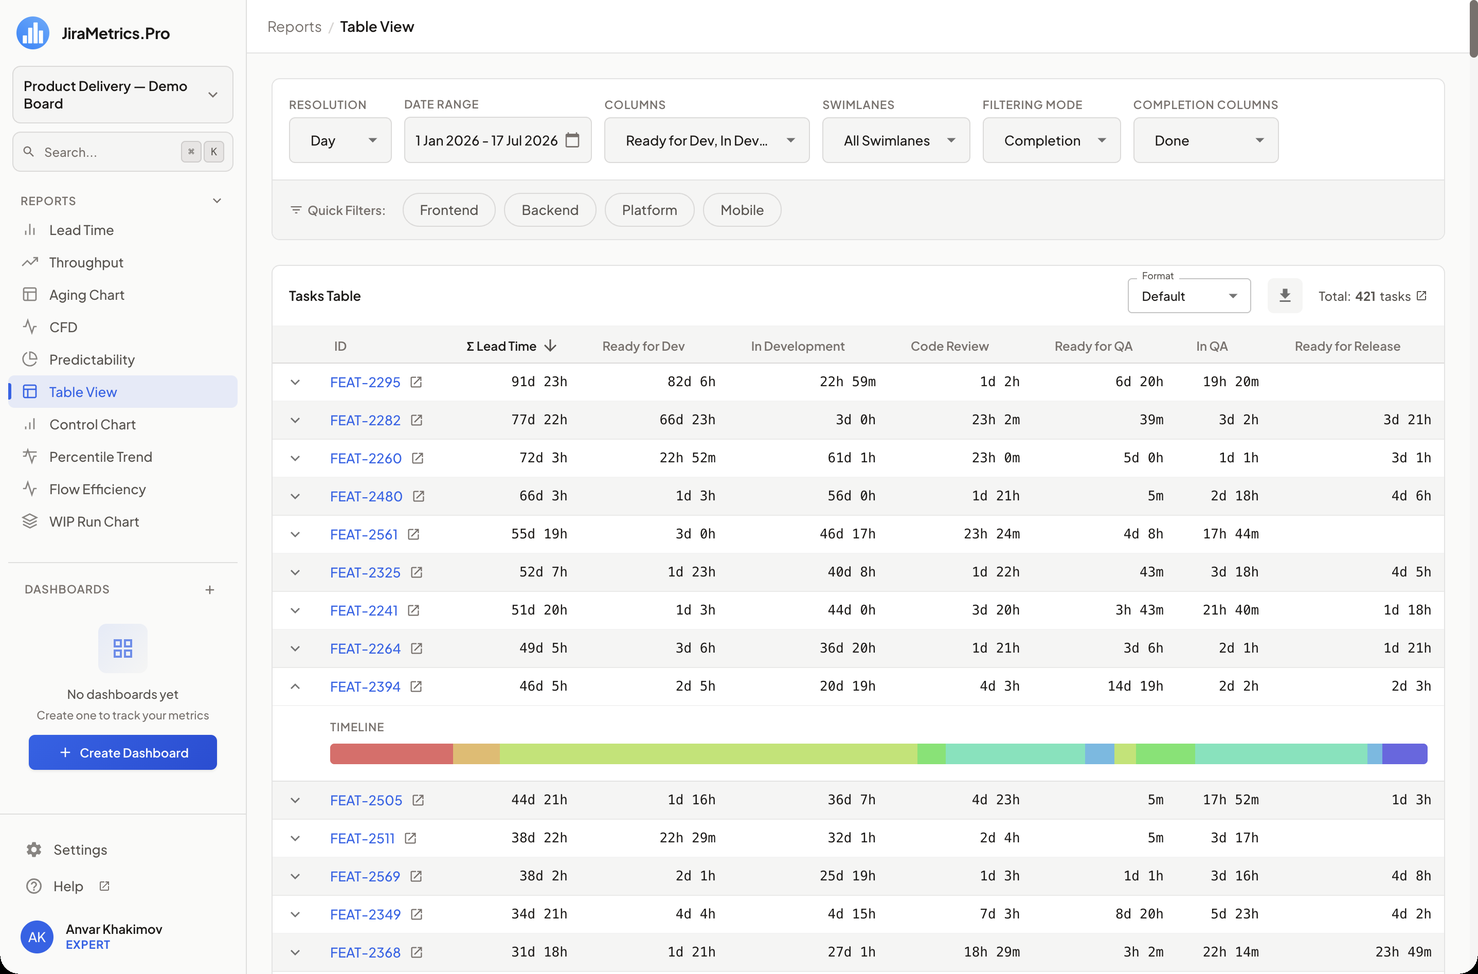
### Table Header [#table-header]
* **ID**: Task identifier. Clicking it opens the [Task Flow](/en/docs/reports/task-flow) dialog. Next to it is a separate arrow icon — it opens the task in Jira in a new tab.
* **Σ Lead Time**: Total task completion time (summed across the selected process columns).
* **Process columns**: Time spent by the task in each selected workflow column.
### Task Rows [#task-rows]
Each row represents an individual task and contains:
* Option to expand to view a detailed timeline.
* Task ID (clicking opens the history) and a separate icon for going to Jira.
* Total task completion time.
* Time spent in each selected process column.
## Detailed Task View [#detailed-task-view]
When expanding a task row, the following is displayed:
### Timeline [#timeline]
* Visual representation of the task's lifecycle.
* Each segment represents time spent in a specific column.
* Color coding of segments corresponds to different process stages.
### Interactive Elements [#interactive-elements]
* Hovering over a timeline segment displays a tooltip with the column name and exact time spent in it.
## Data Interpretation [#data-interpretation]
* **Total lead time**: Allows you to assess the overall duration of task completion.
* **Time in columns**: Helps identify stages where tasks are delayed the longest.
* **Timeline**: Provides a visual representation of the task's passage through various process stages.
## Practical Application [#practical-application]
1. **Process efficiency analysis**: Use sorting by total lead time to identify the longest tasks.
2. **Bottleneck identification**: Analyze time in individual columns to determine stages requiring optimization.
3. **Task comparison**: Use timelines to compare lifecycles of different tasks.
4. **Reporting**: Export data to CSV for creating detailed reports and presentations.
## Conclusion [#conclusion]
The Tasks Table provides a detailed view of each task in your workflow. With this report, you can analyze the efficiency of your development process, identify problem areas, and make informed decisions to optimize workflow.
# Throughput Chart Report (https://jirametrics.pro/en/docs/reports/throughput-chart-report)
## Overview [#overview]
The Throughput Chart is a diagram that displays the number of completed tasks over specific time intervals. This report helps evaluate team performance and identify trends in task delivery speed.
## Chart Structure [#chart-structure]
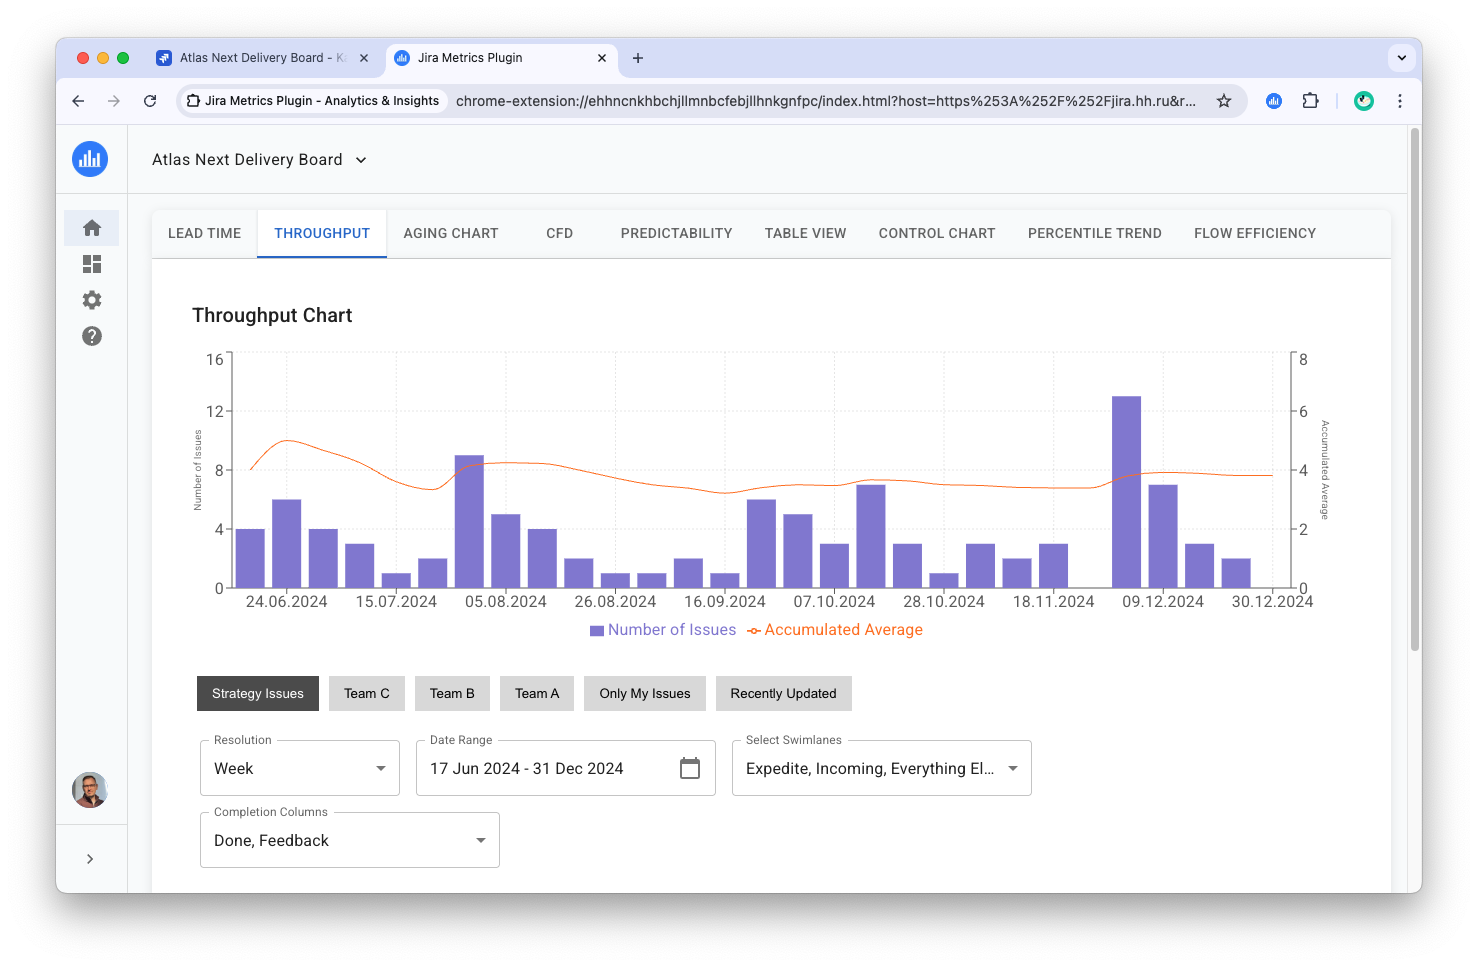
* **X-axis**: Time intervals (days, weeks, or months)
* **Y-axis**: Number of completed tasks for each interval
## Throughput Calculation [#throughput-calculation]
It's important to understand that Throughput is calculated exclusively based on the "Completion" mode:
* Only tasks that have passed through the specified Completion Columns in the given period are counted.
* At least one column must be selected in Completion Columns, otherwise the chart will be empty.
## Report Configuration [#report-configuration]
The following parameters are used to configure the report:
1. **Resolution**: Choose the data grouping interval (day, week, month).
2. **Date Range**: Select the analysis period.
3. **Completion Columns**: Choose columns for analysis. This is a key parameter determining which tasks will be considered completed.
## Metrics Block [#metrics-block]
Above the chart is a metrics block:
* **Total Completed** — the total number of completed tasks for the selected period. Highlighted. Next to it is a trend indicator — this is the **only** metric in the report that is compared with the **previous period** (an interval of the same length immediately before the current one). Growth in the number of completed tasks is shown in green, a decline in red.
* **Peak** — the maximum number of completed tasks in a single period (for example, in the most productive week).
* **Avg / Day** (or Week, Month — depending on the Resolution) — the average number of completed tasks per period.
* **Trend** — a text assessment of the dynamics: `Improving`, `Declining`, or `Stable`. It is calculated **differently** from the arrow on Total Completed: it is the direction of the trend line (linear regression) across all periods of the range. That is why Trend and the arrow on Total Completed may not match — this is normal: Trend answers the question about the dynamics of the whole range, while the arrow compares the last period with the previous one.
For more details on how both kinds of trend are calculated, see the [Metrics and Trends](/en/docs/core-concepts/metrics-and-trends) section.
## Interpreting Results [#interpreting-results]
When analyzing the Throughput Chart, pay attention to the following aspects:
* **High and stable throughput**: Indicates efficient and predictable team work.
* **Low or unstable throughput**: May signal process problems or the need for optimization.
* **Trends**: May reflect changes in processes, team size, or task complexity.
* **Empty chart**: Usually means that no Completion Columns are selected or there were no tasks passing through the specified columns in the selected period.
## Note on Filtering [#note-on-filtering]
Unlike other reports, the Throughput Chart always uses the "Completion" mode for task filtering. The user cannot change this mode but can configure which columns are considered completing through the Completion Columns selection.
## Usage Recommendations [#usage-recommendations]
1. **Choosing the right interval**: Select an appropriate interval (day, week, month) depending on the duration of your tasks and analysis goals.
2. **Trend analysis**: Pay attention to long-term trends. A gradual increase in throughput may indicate process improvement or team growth.
3. **Period comparison**: Use the report to compare performance in different periods, for example, before and after implementing process changes.
4. **Anomaly detection**: Sharp spikes or drops in throughput may indicate special events or problems requiring attention.
5. **Correlation with other metrics**: Consider the Throughput Chart in combination with other metrics, such as Lead Time, to get a more complete picture of process efficiency.
## Conclusion [#conclusion]
The Throughput Chart is a powerful tool for evaluating team performance and analyzing trends in task delivery. Proper use of this report will help you identify areas for improvement and assess the effectiveness of implemented changes in processes.
# WIP Run Chart Report (https://jirametrics.pro/en/docs/reports/wip-run-chart-report)
> **Premium.** The WIP Run Chart report is available on the paid plan.
## Overview [#overview]
The WIP Run Chart shows **how many tasks are in progress at the same time** (Work In Progress, WIP) by day, and how their **average age** changes. The report helps you see team overload and growing "traffic jams": when there are more and more tasks in progress and they are getting older, it is a signal that work is piling up and not being completed.
## Chart Structure [#chart-structure]

A chart with **two Y-axes**:
* **X-axis**: Days.
* **Left Y-axis**: The number of tasks in progress (WIP) — the blue line.
* **Right Y-axis**: The average age of tasks in progress in days — the orange line.
## How It Is Calculated [#how-it-is-calculated]
* For each day, a task is considered **in progress** if on that day it was in one of the selected columns.
* **WIP for a day** = the number of such tasks.
* **Average age** = the average across tasks of the accumulated time they have spent in the selected columns by that day.
## Metrics of This Report [#metrics-of-this-report]
Below the chart there is a metrics block:
* **Current WIP** — the WIP on the last day of the range. Highlighted.
* **Avg WIP** — the average WIP value across all days.
* **Range** — the minimum and maximum daily WIP over the range.
* **Trend** — the direction of WIP dynamics. The average WIP over the **last quarter** of the range is compared with the **first quarter** (at least 4 days of data are required): a change of more than 5% in either direction → `Increasing` / `Decreasing`, otherwise `Stable`. A decrease in WIP is an improvement (green ↓), an increase is a deterioration (red ↑).
This is a trend "within the selected range", not a comparison with a separate previous period. For more details, see the [Metrics and Trends](/en/docs/core-concepts/metrics-and-trends) section.
## Interactive Elements [#interactive-elements]
When hovering over a day, a tooltip appears:
* **Date**
* **WIP Count** — the number of tasks in progress on that day
* **Average Age** — the average age of tasks (hours if less than a day, otherwise days)
## Impact of Settings [#impact-of-settings]
* **Selected columns** determine which columns are considered "in progress".
* **Date range** sets the grid of days.
* The report has no settings of its own. There is no WIP limit line in this report — it exists on the corresponding dashboard widget.
## Special Cases [#special-cases]
* If there is no data, the report shows an empty state.
* If a task was not yet on the board on a particular day, it is not counted on that day.
## Usage Recommendations [#usage-recommendations]
1. Keep WIP limited — the fewer tasks in progress at the same time, the faster they are completed.
2. **Growing WIP together with growing age** is an alarming signal: tasks are piling up and aging, the flow is slowing down.
3. Compare WIP with throughput (the Throughput report): if more work is taken on than can be completed, WIP will grow.